How do we use this? · Background paper 5 · Argument 5 of 6
Your corrections are the most valuable data in your company.
Background to the post of the same name, drawn from the working paper How Do We Use This?
Preprint. Reviewed by a panel of AI reviewers (Claude Opus 5.5) and revised 7 October 2026; not externally peer reviewed. Reproduced from the working paper as revised 7 October 2026.
In plain terms
Every correction a person makes to an AI system records what was wrong, why, and what right looked like. No preference click carries that. Model developers do collect richer feedback, including full conversations and expert-graded work, but not your firm’s record of its corrections and what followed them. No lab can buy that.
The practice studied kept its full record: 8,221 operator turns over six months, with an answer key the operator wrote blind. That record is the only reason it knows the detector flagged about 48% of the operator’s turns as corrective, roughly a third adjusted, while agents logged misses on 1.76%.
Our position: the depth of one owner’s corrections is data broad feedback cannot recover, and it compounds only if the record survives the session. The record is private and one operator’s, a case rather than a population, and the practice has not yet shown a recorded lesson changing later behavior.
About this paper. This is one of ten short background papers to a series of plain-English posts: six argument papers (background papers 1 to 6) and four primers (7, 8, 9, then 0). Every passage below is reproduced word for word from the working paper How Do We Use This? (Atkinson, 2026) as revised 7 October 2026, with that paper’s section, figure and table numbers. Passages are excerpts; a reference to anything not reproduced here resolves in the full paper. Tags such as “Our position” or “Conjecture” say what kind of support a claim has. Only the plain-terms summary, the box of terms, the post’s figure, and the section labels were written for this part. The title is the author’s position, argued rather than measured. The full paper is linked from every post in the series.
Terms used here
Operator. The human who directs the agents and approves their consequential changes; here, the author.
Seat. The practice’s word for one running AI agent session, with its own context window and its own identifier.
Boot page, boot set. The boot page is the start-up page for the practice’s agent sessions; the boot set is the two rule-bearing documents every new session must load.
0-for-7. The boot page’s own record that a written rule was missed seven times on 12 July 2026, which it counts as one act rather than seven failures.
Stopping moment. The turn at which an agent states its answer as final without a further search or read.
Folding. A model giving up its position when challenged, whether or not the challenge is right.
The floor. A gap of one session between appearances of a tracked error class: it came back in the very next session. Recurrence, the program’s outcome measure, is how soon such a class comes back.
Detector, blind key. The detector is a local model that labels every operator turn as corrective or not. The blind key is a sample of turns the operator labeled by hand without seeing any model’s labels (195 graded rows); it measures how often the detector is right, not whether the agents’ answers were.
The counterweight. The paper’s proposed challenge to an agent at its stopping moment, not yet deployed. Its three clauses: (a) external to the agent’s own output; (b) firing on actual error, not on the agent’s confidence; (c) delivered at the stopping moment, at a rate above the ambient error rate.
H1 to H3. The paper’s hypotheses about the counterweight: H1, it is a projection of the operator’s judgment; H2, it is a control problem rather than a voting problem; H3, a reversal is not a correction.
From §7 · The proposition, and the evidence for it
7P5Depth of record over breadth of feedback
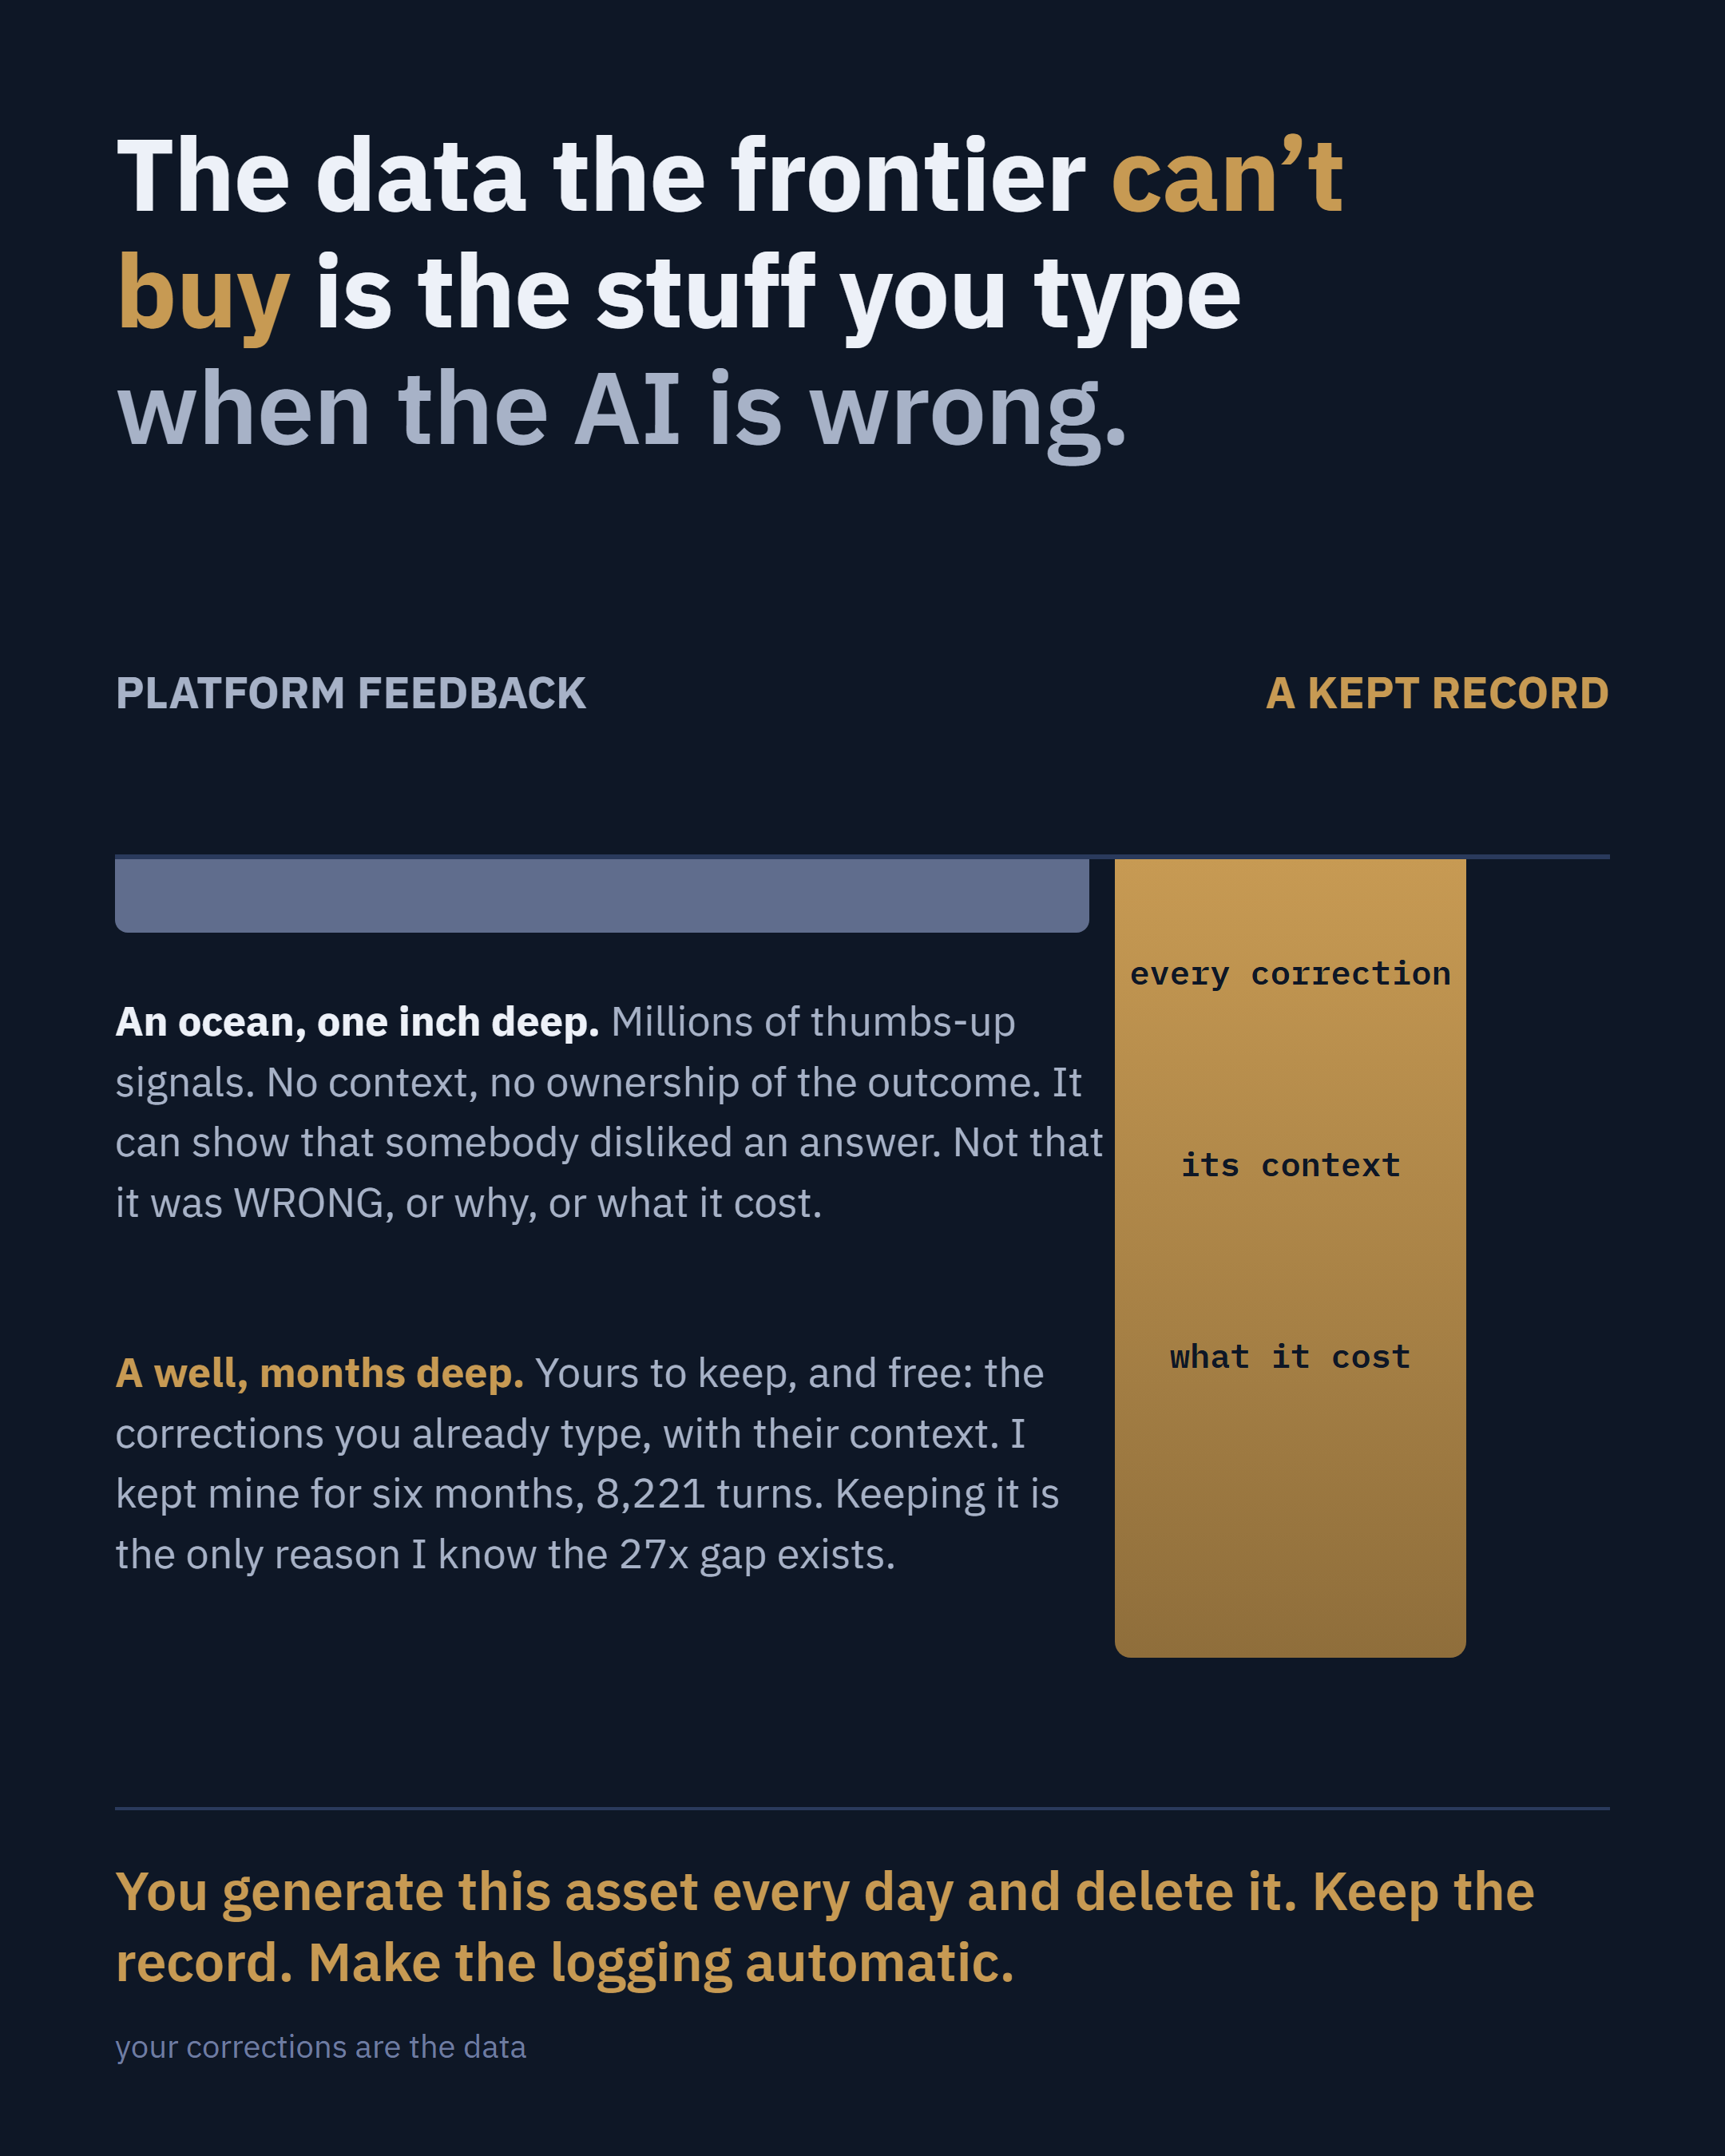
The operator’s proposition: “The data the frontier can’t buy.”
The developers of frontier models collect feedback at a breadth no single practice can match, richer than a click: preference ratings, full conversations and coding sessions from users who allow their use, and expert work graded by reviewers. What that breadth cannot supply is depth: one continuous operator, consequences observed over months, and the owner’s own adjudication of what went wrong. Our position: that depth is what a single operator’s record has, and it makes an operator’s corrections the most valuable data in the company.
7.1From the logsWhat one operator’s record holds
The record described in §2.2 has what a broad collection lacks: one operator; the full surrounding record of what the agent read and held; ownership of the consequences; a continuous identity over six months; and a detector of corrective turns graded against a key the operator wrote blind. The key is narrow: 195 of the 8,221 operator turns, about 2.4%; it grades whether a turn was corrective, not whether the answer was wrong; and its single rater is also the subject, analyst and owner. Such a record can say that an answer was wrong, why, what the model had read, and what happened next, though not every row carries every field (§5.2). It is a case record and a method, not a population, and it is private (see Data availability).
7.2From recent workThe gap
The oversight studies in §2.1 recruit reviewers for a task built for the study, on a study platform, over weeks. Buser et al. (2025), whose threat-image-projection design seeds threats into a working screening queue and scores per named screener, is still a constructed detection task with recruited staff. The 2026 agent-stopping literature of §2.1 measures the phenomenon far more precisely than this practice can, but it measures it on benchmarks: HotpotQA, SWE-bench, WebShop, constructed multi-constraint queries, with correctness supplied by the benchmark. This paper claims no priority. A novelty claim is an absence claim, an absence claim is a report about a search, and a search stops when it has enough for a defensible related-work section, which is this paper’s thesis applied to its own bibliography. We do not make one.
What can be said without a search behind it is what the record contains. One operator. A live team of agents on consequential work. Six continuous months. Corrections labeled by the person who owns the outcome, against a key that operator wrote blind. Every method used to read it, from seeded faults to per-individual scoring to pre-registration to live-queue measurement to evidence-gated commitment, is established elsewhere and in several cases better evidenced elsewhere (§2.1). The cost of the setting is the same fact as its value: ecological validity and longitudinal depth, at N = 1 and with one rater. Readers should assume that any mechanism described here has a better-evidenced counterpart in the literature of §2.1, and should treat this paper as a field record rather than as a claim to have been first at anything.
From §2.2 · What the record holds
2.2The practice and its data
The practice is a one-person engineering and consulting company. Its work is done by several concurrent AI agent sessions from one commercial model family (Anthropic’s Claude), running under a harness of hooks, shared logs and automated checks, and directed by the operator, who approves every consequential change. The planned extension of the evaluation adds three co-researchers from outside the company (§10.8). Table 1 fixes the vocabulary used in the rest of the paper.
| Term | Meaning here |
|---|---|
| Agent (seat) | One running AI agent session, with its own context window and its own identifier. The practice’s records call an agent session a seat. |
| Operator | The human who directs the agents and approves their consequential changes; the author. |
| The logs | The durable records an agent does not write about itself: session transcripts, an event log, version-control history, a log of caught errors, and a log of the operator’s decisions. |
| Stopping moment | The turn at which an agent emits a terminal assertion without a further retrieval act. |
| Automated check | A check that runs at a boundary, for example when an agent ends its turn or at a commit, and can refuse or flag. |
| Catch | The first surfacing of an error, whether by the operator, another agent, an automated check, or the agent itself. |
| Implemented, designed | Whether a component exists in the running system or only in its design. The practice’s architecture model marks every component one way or the other, and this paper does the same. |
| Sample frame | The set of records a rate is computed over; here, 8,221 operator turns in the chat-lane conversation file of the export of 26 August 2026 (§2.2). |
| Answer key (blind key) | Exchanges from the frame that the operator labeled by hand without seeing any model’s labels: 199 written, 195 graded after a repair (§2.2). |
| Detector | The local model that labels each operator turn as corrective or not. Recall is the share of the key’s corrective turns it flags; precision, the share of its flags the key confirms. |
| Counterweight | A challenge aimed at the stopping moment (§8), with three clauses: (a) external to the agent’s own output; (b) discriminates on actual error, not on the agent’s confidence; (c) delivered at the stopping moment, at a rate above the ambient error rate. |
| H1 to H3 | The hypotheses of §8.4: H1, the counterweight is a projection of the operator’s judgment; H2, it is a control problem rather than a voting problem; H3, a reversal is not a correction. |
| Recurrence | The program’s primary outcome: how soon a named error class comes back, read from the ordered sessions in which it appears (§5.2). |
The operator’s corrections are the data of interest. The primary sample frame is the chat-lane conversation file of the practice’s export of 26 August 2026: 8,221 operator turns in 281 conversations between 9 February and 26 August 2026, pinned by SHA-256 hash and reproduced to the turn by an independent count. Design-lane conversations are excluded from this frame, so rates over it describe the chat lane rather than all of the operator’s work. A second corpus holds 294 code-agent session transcripts (count of 30 August 2026). The operator wrote a 199-exchange answer key blind, without seeing any model’s labels, on a systematic sample of the frame. Its one rater is the operator, also the study’s subject and author (§10.6). 199 rows were authored; a documented repair on 31 August 2026 that removed unanswerable rows left 195 in the file the detector was graded against. That repair is not fully described, and it changed more than its four removed rows could account for, though the adjusted estimate barely depends on it (§6.2). Where a figure below depends on the grading, it depends on the 195. The practice’s event log held 30,377 events when counted at its files for this revision (11 September 2026, US Eastern; 2,640 in the live file and 27,737 archived), and its architecture is documented in a DoDAF 2.02 model generated from the codebase, with 35 views and 351 data-dictionary elements, each marked implemented or designed. Both figures are the generating instrument’s own headline and both disagree slightly with its own itemization: the package’s view index lists a thirty-sixth view, and the registry’s per-type element counts sum to 354. We quote the headline and record the discrepancy rather than silently picking whichever number reads better. Decisions cited in this paper are dated.
The readings in §3 to §7 come from instruments the practice built and operates. They are descriptive and exploratory: none is the primary outcome, and all of them are exposed to the threats set out in §11. Table 2 maps each proposition to the readings and the published work it rests on.
| Proposition | From the practice’s logs | From recent work | Status | § | |
|---|---|---|---|---|---|
| P1 | The missing weight is correctness | The detector flagged about 48% of operator turns as corrective; roughly a third after adjusting for its error ratesrecall 93%, precision 64% on the 195 graded key rows | Mehta (2026) | rate measured; link inferred | 3 |
| P2 | Direction, not capability | Of five misses in one window, two surfaced by the operator outright, one only after the operator pointed at a silent check, and two by an automated check and the agent’s own checkhand-picked case series, 4 to 5 Sep 2026; not a rate | Kelley & Riedl (2026) | inferred (cases) | 4 |
| P3 | Rules drift. Incentives and boundaries hold | Rule adherence across the corpus is not measured (§5.1); the two tracked error classes came back in the very next session in 48 of 75 intervals, against about 40 expected from prevalence alone (status board, 11 Sep, 18:57 UTC; §5.2)rule history; recurrence measure | Wang & Huang (2026); Lamparth et al. (2026) | recurrence measured; P3 a conjecture | 5 |
| P4 | An AI grading its own homework isn’t being measured | 75 of 579 sessions recorded loading their context; flagged corrective turns ran near 27× the corrections the system logged (about 19× adjusted; the flagged turns are the broader category, §6.2); four failures of the practice’s own checksevent log; pushback census | Ivanov & Africa (2026); Denisov-Blanch et al. (2026); He et al. (2026); Kenton et al. (2026) | counts measured; link inferred | 6 |
| P5 | Depth of record over breadth of feedback | 8,221 operator turns over six months, and a key of 199 exchanges the operator wrote blind, 195 of them gradedexport of 26 Aug 2026 | No priority claimed (§7.2) | conjecture | 7 |
From §3.1 · How much of it is correction
3.1From the logsHow much correction the operator supplies
A census of the sample frame described in §2.2 (8,221 operator turns) measured how often an operator turn carried corrective signal, a correction, a reframing or a pointed challenge to what the agent had just said. A local model labeled every turn, and the detector was graded against the operator’s blind key, 195 rows after the repair of §2.2, at 93% recall and 64% precision. It flagged about 48% of operator turns. Adjusting for the detector’s measured precision and recall lowers that to roughly a third (0.48 × 0.64 / 0.93 ≈ 0.33), an inference that assumes the key’s mix of turns matches the frame’s, on a grade that may predate the join repair (§6.2, §10.6). The signal is corrective in the broad sense. The operator’s own second pass over a stratified sample labels most non-routine turns as bundles of method correction, reframing and teaching, and whether the finer channels are reliably separable from one another is unsettled, because the reading that said they were not has since been traced to a join defect (§10.6). So the reading is that roughly a third of the operator’s turns were spent redirecting an agent rather than routing it, not that a third of the agents’ answers were wrong. That each such turn followed a premature stop is an inference, not a measurement; on that inference, the agents stopped where their answers were defensible and the operator supplied the rest, by hand. Counting the corrective turns that cite evidence the agent could have retrieved before stopping would test it; that count has not been made.
From §6.2 · How much of it the system logged by itself
6.2From the logsThe logging gap, with its ruler
The 27× figure has been quoted more often than it has been explained, so we give its full provenance. The numerator is the operator-pushback rate from a census of the 8,221 operator turns of one chat-lane conversation file (the frame of §2.2). A local seven-billion-parameter model labeled every turn, and the pushback detector was graded against the operator’s blind key at 84% recall and 59% precision, and at 93% recall and 64% precision on the 195 rows left after a documented repair of the key on 31 August 2026. It flagged about 48% of operator turns. The 195-row grade has not been re-checked since the join repair of 11 September (§10.6); on the earlier grade the estimate below barely moves (0.48 × 0.59 / 0.84 ≈ 0.34, against 0.33). The denominator is the rate of corrections the system itself logged: misses in the practice’s session-health event log, which records one only when an agent runs a logging command (§10.9), set against the same operator turns, at 1.76%.
The two ends come from different instruments and different stores, and they count different things: the numerator is corrective signal in the broad sense of §3.1 (correction, reframing, pointed challenge and teaching), the denominator only logged misses, so part of the gap is definitional. The numerator is also uncorrected for the detector’s precision. Correcting the observed flag rate by the detector’s measured precision and recall on the blind key, which was drawn systematically from the same frame, puts the rate at roughly a third of operator turns and the ratio near 19.
r̂ = robs × P / R = 0.48 × 0.64 / 0.93 ≈ 0.33
ratio = r̂ / 0.0176 ≈ 19
robs is the detector’s flag rate, P and R its precision and recall against the 195-row blind key, and 0.0176 the rate the system logged over the same turns. The correction assumes the key is representative of the frame, which is the assumption §11 records as a threat. No interval is attached yet; the uncertainty in P and R carries into both figures.
We therefore report the gap as corrective signal per logged miss, with this ruler attached, and never as a miss rate; we read it as an indication of logging loss. Either way the direction holds: the corrective signal is far more abundant than the system’s record of it. That makes a study of the operator’s natural corrections viable, and it makes what an agent reports about itself the unreliable minority of the record.
From §5.2 · Why a lesson needs its source attached
A lesson written into the record is a rule of the first kind, one an agent must go and read, and case 3 of Table 3 shows one failing soon after it was read. The lesson was written down; it just was not anywhere that mattered. The practice’s learning instrument makes the same point from the other side: of eight lessons ratified into the merged store, zero are currently measurable for whether behavior changed, because promotion dropped the citation linking a lesson to the miss that bought it, so the entries join to nothing. The instrument reports that as eight unmeasurable rather than as a rate, which is the correct refusal and also an admission that the loop cannot yet tell whether a lesson lands.
From §8.4 · What the record is for
H1, the counterweight is a projection of the operator’s judgment. The agents working under the harness generate a corpus of the operator’s corrections in the course of ordinary work; a nightly consolidation of the day’s corrections produces an updated projection of that judgment, and the projection, delivered into an agent’s context at the stopping moment, is the counterweight. The main path, delivery into the context window, needs neither weights nor logits. A secondary training path, steering a fixed model through a smaller tuned one (proxy-tuning, for example), needs the large model’s full next-token distribution at each step, which closed APIs generally do not expose; in practice it means open-weight models, and a review of model terms of use is a gate on it.
From §13 · What would overturn each claim, and what transfers
| Rests on | Would be overturned by | Status | |
|---|---|---|---|
| P1 | Corrective signal flagged in ~48% of operator turns, roughly a third adjusted (§3.1); Mehta (2026) | A build that prices correctness at the stop and still terminates early; weakened if few corrections point to evidence the agent could have retrieved before it stopped | count measured; link inferred |
| P2 | The case series (§4.1; five hand-picked cases, not a rate); Kelley & Riedl (2026) | The same agents catching their own premature stops without operator direction | inferred |
| P3 | A tracked error class back in the very next session in 48 of 75 intervals (§5.2); the read-versus-injected mechanism, not a rate (§5.1); Wang & Huang (2026) | A remembered rule that holds across sessions where only a boundary now does | recurrence measured; link a conjecture |
| P4 | Load records in 75 of 579 sessions; the logging gap, about 19× adjusted (27× raw); four instrument failures (§6) | A self-report that tracks the logs it claims to summarize | counts measured; link inferred |
| P5 | The 8,221 operator turns of the six-month chat-lane log and the blind answer key (§2.2, §7) | A broad feedback dataset that links one owner’s corrections on consequential work to what followed, over months | conjecture |
What transfers, if anything does. Our position: three rules earned here rest on argument and on the work cited, not on this practice’s N of 1 alone. Rulebooks are theater; boundaries and incentives are not: a boundary that refuses and records its refusal outlasts a memo that asks an agent to remember (§5; from one practice, and the least tested of the three). A challenge must cite evidence the challenged agent can open, or it is an opinion wearing a citation (§8.2), because an unconstrained critic can invent its evidence (Kenton et al., 2026). And an outside checker must be calibrated against known-false cases before it is allowed to gate anything, because a checker built from the same class of model may simply agree with the claim it is shown (§9; Panickssery et al., 2024; Knight & Leveson, 1986). Conjecture: every team that clears its chat history lives inside its own version of the gap between the corrective signal its people supply and the corrections its system logs; that is the first thing a replication would count.
From §11 · Limits
Construct. The primary outcome, recurrence (how soon a named error class comes back in a later session, §5.2), is a proxy. Recurrence can fall because an error class genuinely recurs less, or because detection of the class degraded. The mitigations are an independent adjudication arm that does not share the detector’s blind spots, and the per-class series, in which a detection collapse shows as a simultaneous fall across classes. Srinivasan and Paragiri (2026) give the general form of this hazard for agent-driven search: where validity lives in disaggregated structure, an aggregate reduction can rank the wrong candidate first, the headline number improving while the structure beneath it inverts. Their remedy is an external control loop that audits disaggregated behavior after the agent has decided and can reopen a run the agent declared finished, the shape of the primary study’s off-target condition (Study 3, §10.4): targeted error classes must fall without a matching fall in untargeted ones. The pushback reading behind §3.1 and §6.2 comes from a machine labeler with 64% precision on the blind key (195 rows the operator graded blind, §2.2), and its adjusted figure depends on that key being representative of the frame, the 8,221 operator turns of the chat-lane log; no re-grade of the labeler on the repaired join of §10.6 is reported. The calibration set’s labels are mechanical: they establish whether a test passed, not whether the agent’s work was correct.
External. One operator, one domain, one harness, one model family for the agents. Nothing here generalizes to other operators without replication, and the multiple-baseline extension (§10.2: staggered starts for the operator and three co-researchers) raises N to four within one organization, not to a population. The setting’s ecological validity is bought with exactly this cost.
Open questions. Readings of the working paper’s own records that cut against a position it takes, collected here rather than beside the positions they concern and left open; section numbers are the working paper’s.
- §6.2, the logging gap. Part of the gap between logged misses and flagged corrections is definitional, and the §6.2 counts show self-report to be sparse, not wrong; the case that it is wrong rests on §6.3 to §6.5.
How to cite this part. Atkinson, B. (2026). Your corrections are the most valuable data in your company. Background paper 5 to How do we use this? Working paper, Wolfberg LLC.
Disclosure. Drafting and literature synthesis were assisted by AI models (Claude, Anthropic) working under the author’s direction; the author is responsible for the content. The works in the References were read in full by AI reading agents working under the author’s direction, and quotations and numbers taken from them were checked against the saved full text. The prior-art works listed under Prior art are cited at the level of an established concept and its origin: each was verified for author, title, year and venue, but not read in full, and no numeric claim rests on any of them. Software documentation, source code and press accounts are listed under their own headings and were read at the linked pages. Every reference below carries a link, and every arXiv identifier and DOI was resolved against its registry, with title and first author matched, on 23 September 2026.
Competing interests. The author owns Wolfberg LLC, the practice studied.
Data availability. The practice’s logs contain client work and personal records. They are private and are not offered for sale or sharing. The measures are described in enough detail to be reimplemented, and figures from the practice are reported as of the dates given. What is available is the design: the clauses of §8.1, the evidence contract and admission checks of §8.5, and the decision rules of §10.4 are stated in this working paper fully enough to be rebuilt without access to the logs; the background papers reproduce only parts of them.
Corrections to the full working paper. The notes below record corrections to the working paper as a whole; some concern sections not reproduced in this part.
Corrections, 23 September 2026. No figure and no finding changed. The paper was retitled; earlier revisions were titled The Stop Problem: Defensible Is Not Correct, and the stop problem remains this paper’s name for the failure it studies. The Anthropic interview in §2.3 aired on 13 September, not over a weekend of 13 and 14 September; the web article is stamped 14 September. The essay listed under Prior art is by Ryan Forstie; an earlier revision gave the initial K. The completion evaluator in §8.3 is documented as a Claude Code feature, whose agent loop the Claude Agent SDK embeds; an earlier revision attributed it to the SDK directly. Two works in the References, Graves (2016) and Liu (2026), were listed without being cited in the text; each is now cited where it bears (§2.1, §8.3). Links were added to every press, documentation and prior-art source. A duplicated section number in §10 was corrected.
Corrections, 25 September 2026. No figure changed. §8.3 said that the human-in-the-loop primitives across the three frameworks surveyed gave a developer nothing to require a person to confirm finished work. That holds for the OpenAI Agents SDK and the Claude Agent SDK. It does not hold for CrewAI, whose task documentation, already cited as CrewAI (2026b), offers an opt-in setting for a human to review the agent’s final answer; §8.3 now says so.
Corrections, 7 October 2026. After review by a panel of AI reviewers: a quotation in §4.2 from Mytsyk, Zhang and Krishnamurthy (2026) carried words its source does not contain (“or truthfulness, only about sycophancy”) and now reads as the source does, “Our results say nothing about correctness”; the point it supports is unchanged. The §8.3 design rule is no longer stated as a law: an instrument the measured party can operate tends to rot; one it cannot alter is harder to game, though not immune. Zhang et al. (2026) is now read as a gain from training, not from moving a check outside the agent (§8.3, Figures 10 and 11). Laban et al. (2023) replaces Kelley and Riedl (2026), whose tasks have no ground truth, in Table 5 and H3. The 48% is now the share of operator turns the detector flagged, roughly a third adjusted; the 27× logging gap is about 19× adjusted and partly definitional. Table 9 separates measured counts from interpreted links, §13 offers its design rules as hypotheses, and the Disclosure says who read the cited works. A second pass the same day restored, in the author’s wording, positions that revision had softened for reasons other than fact, and labelled each for status (our position, conjecture, from one practice, measured) instead of hedging it; Table 9 now carries a Status column and §13 states its design rules as our position. Every factual correction above stands.
Works cited in this part (keys, including letter suffixes such as 2026b, follow the full paper’s reference list)
References
- Denisov-Blanch, Y., Kazdan, J., Chudnovsky, J., Schaeffer, R., Guan, S., Adeshina, S., & Koyejo, S. (2026). Consensus is not verification: Why crowd wisdom strategies fail for LLM truthfulness. arXiv:2603.06612. arxiv.org/abs/2603.06612
- He, C., Chen, Z., Yang, Z., Qiao, S., Ju, M., Liu, J., Wen, D., & Liu, G. (2026). Minority Sentinel: When to overturn majority voting in multi-agent LLM debates. AgentSearch Workshop at SIGIR 2026. arXiv:2606.29270. arxiv.org/abs/2606.29270
- Ivanov, I., & Africa, D. D. (2026). LURE: Live-usage replay evaluations for reducing evaluation awareness. arXiv:2605.26438. arxiv.org/abs/2605.26438
- Kelley, S. W., & Riedl, C. (2026). Personalization increases affective alignment but has role-dependent effects on epistemic independence in LLMs. arXiv:2603.00024. arxiv.org/abs/2603.00024
- Kenton, Z., Janzer, L., Greig, R., Teh, T. H., Tyshchuk, K., Brown-Cohen, J., Edwards, H., Rajamanoharan, S., Siegel, N. Y., Jaques, N., et al. (2026). Debate training reduces reward hacking in RLAIF. arXiv:2608.17776. arxiv.org/abs/2608.17776
- Lamparth, M., Fein, D., Haupt, A., Hussing, M., & Kochenderfer, M. J. (2026). Reward bias substitution: Single-axis bias mitigations redirect optimization pressure. arXiv:2605.27996. arxiv.org/abs/2605.27996
- Mehta, A. (2026). When agents commit too soon: Diagnosing premature commitment in LLM agents. Snowflake AI Research. arXiv:2606.22936. arxiv.org/abs/2606.22936
- Panickssery, A., Bowman, S. R., & Feng, S. (2024). LLM evaluators recognize and favor their own generations. arXiv:2404.13076. arxiv.org/abs/2404.13076
- Srinivasan, A., & Paragiri, D. (2026). Search discipline for long-horizon research agents. arXiv:2606.11522. arxiv.org/abs/2606.11522
- Wang, J., & Huang, J. (2026). Reward hacking as equilibrium under finite evaluation. arXiv:2603.28063. arxiv.org/abs/2603.28063
Prior art (cited at concept level; verified for author, title, year and venue, not read in full)
- Knight, J. C., & Leveson, N. G. (1986). An experimental evaluation of the assumption of independence in multiversion programming. IEEE Transactions on Software Engineering, SE-12(1), 96–109. doi.org/10.1109/TSE.1986.6312924
- Buser, D., Schwaninger, A., Rehor, V., & Sterchi, Y. (2025). Reliability and validity of threat image projection data as a measure of performance in X-ray baggage screening. Transportation Research Part A: Policy and Practice, 200, Article 104640. doi.org/10.1016/j.tra.2025.104640 Named as an ancestor of the live-queue method only; a corrigendum (doi.org/10.1016/j.tra.2025.104683) is unread, so no figure from it is cited anywhere in this paper.