Who Caught It
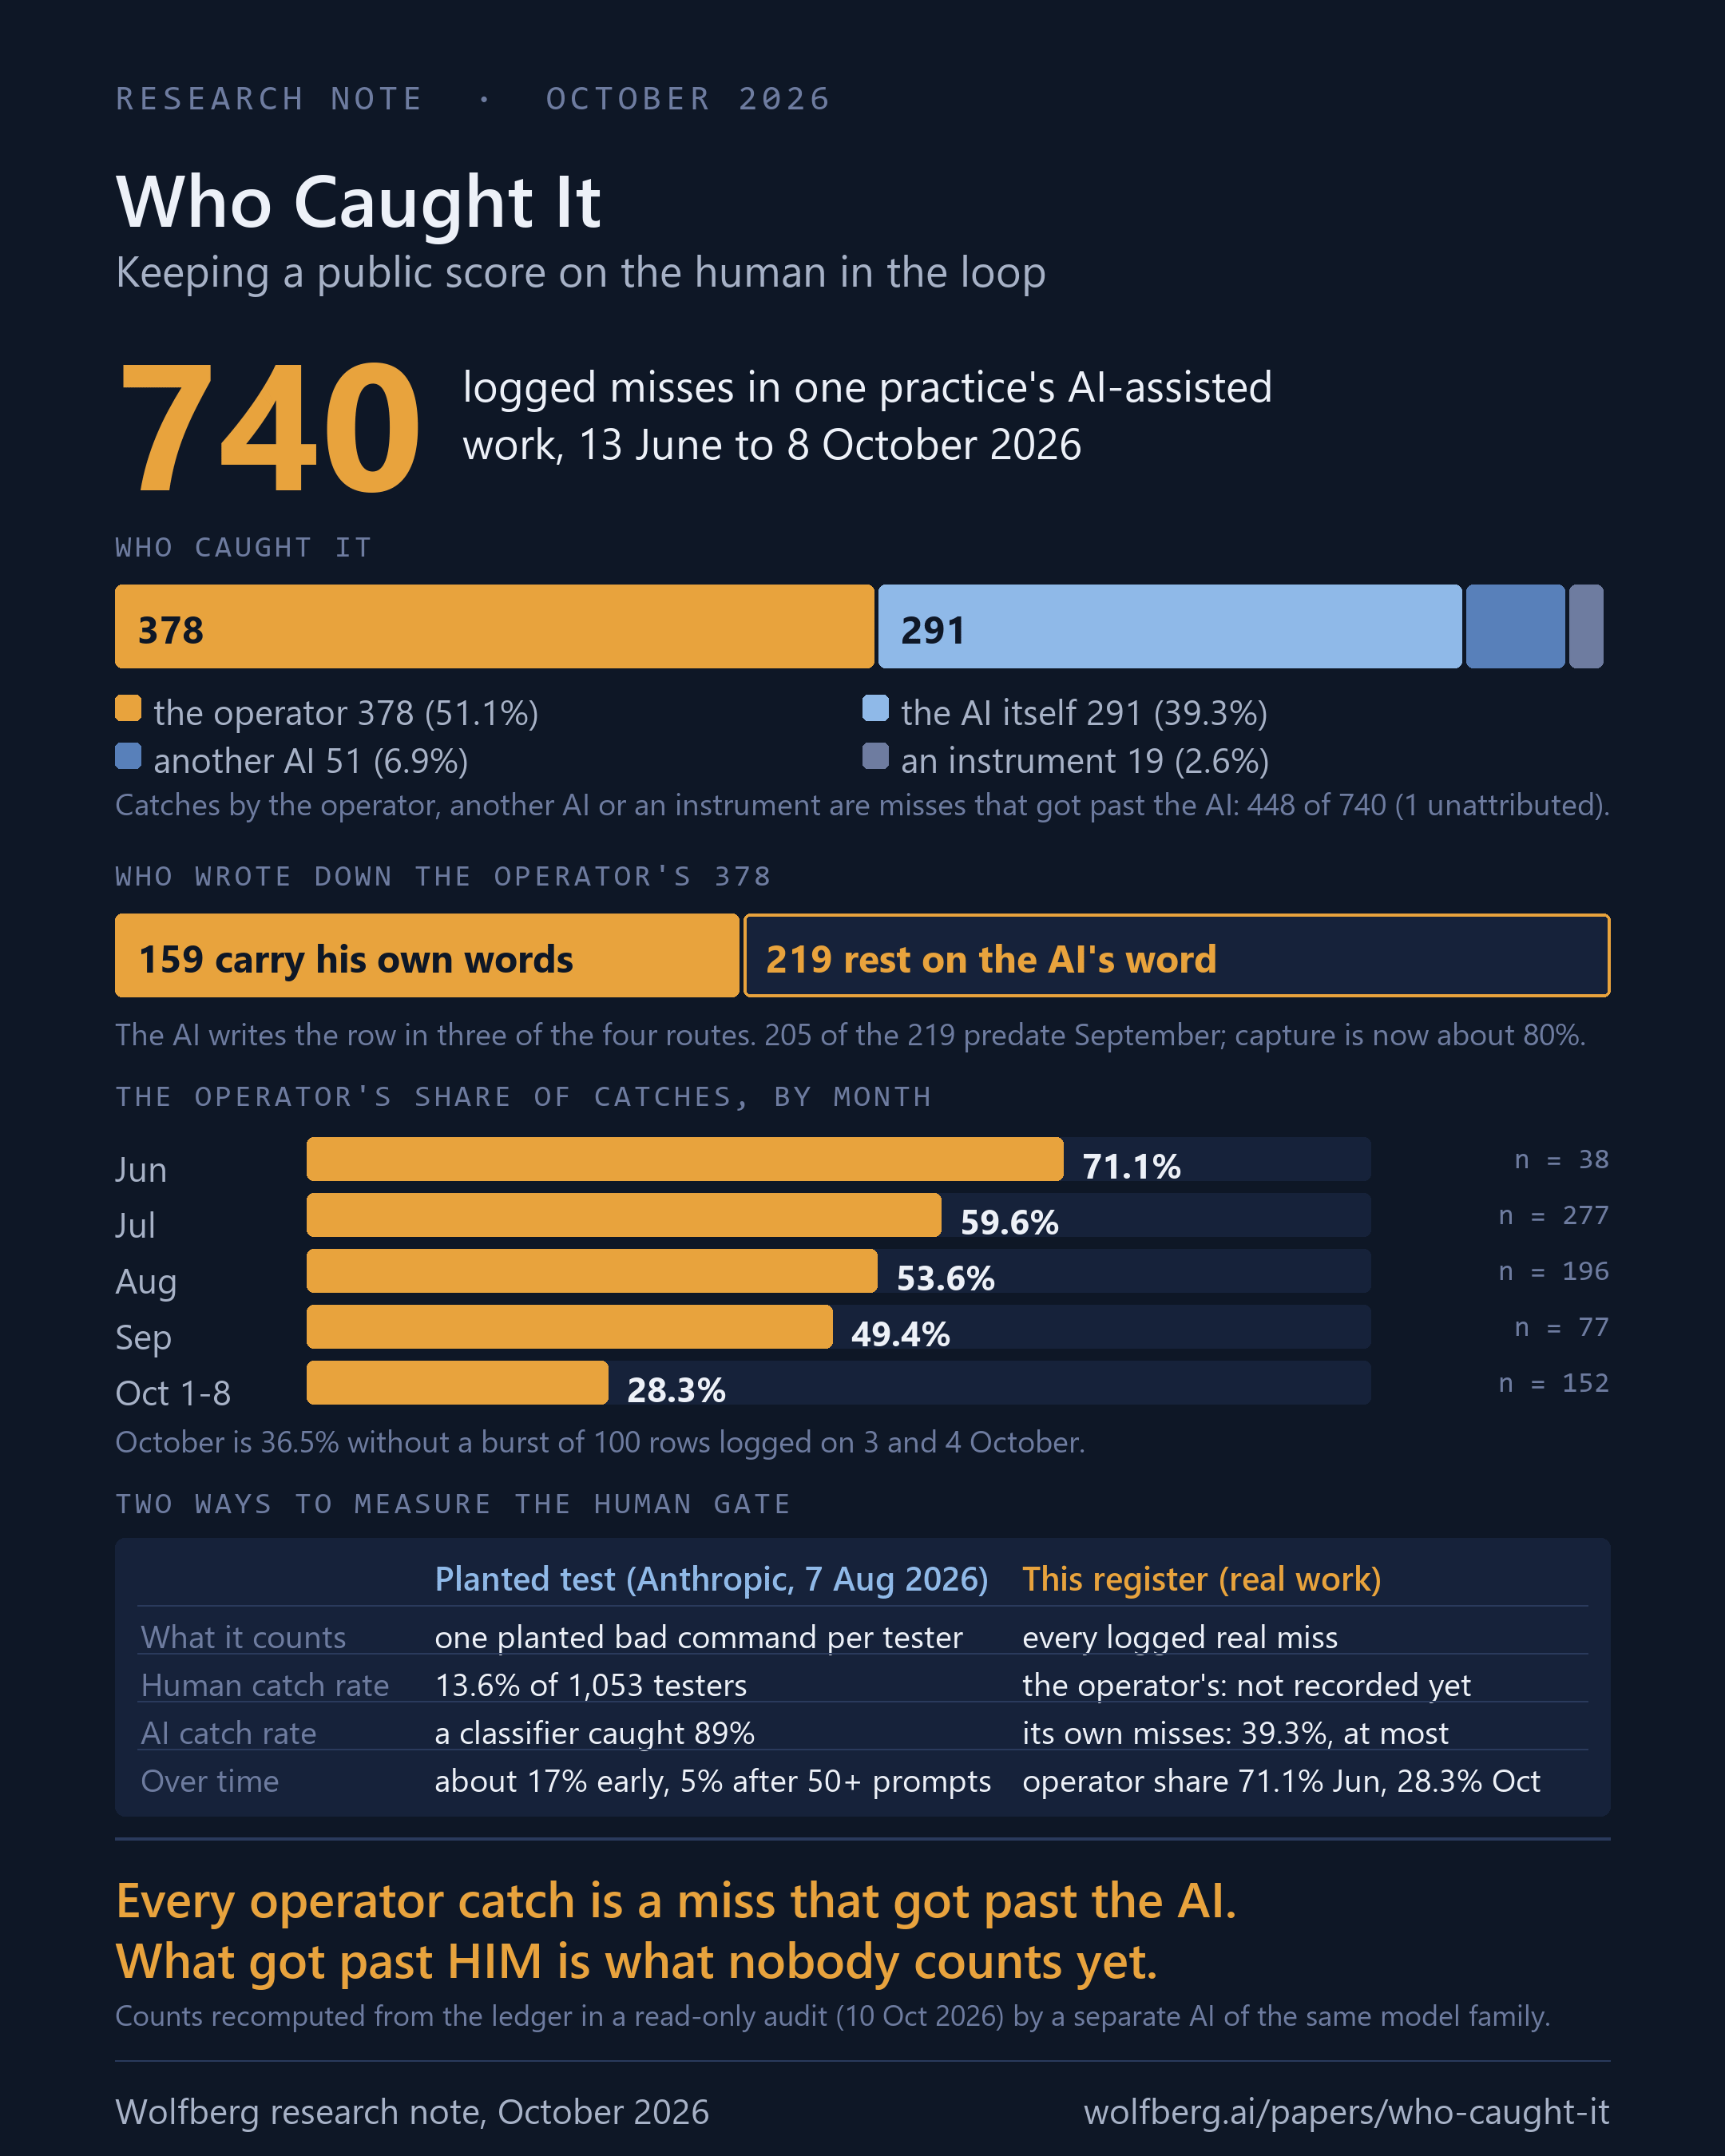
How do you know the human in the loop is actually catching what your AI misses? Best recent answer: a planted test. In August, Anthropic put one dangerous command in front of each of 1,053 paid testers, and humans caught it 13.6% of the time. Good test! But it's ONE test, planted, in a test environment. That's not a Tuesday on real work. A human WATCHING the loop isn't a human IN it.
So I keep score on real work. Every logged miss in my AI-assisted work goes into a public, hash-chained register (wolfberg.ai/register), and every row says who caught it: me, the AI itself, another AI, or an instrument.
And the count is NOT the interesting part. The chain is. The AI checks itself first, and whatever gets past it gets caught by another AI, an instrument, or me. So every catch of mine is a miss that got past the AI...which means the AI has a real catch rate: about 4 in 10 of its own misses, at most.
Side by side, planted test | my register:
- What it measures: a planted bad item, once, in a test | real misses, who caught them, in order, all the time
- Catch rate: humans 13.6% of 1,053 testers (Anthropic, Aug 2026) | the AI 39.3% of its own misses, at most. Mine isn't recorded yet.
A separate AI session audited the register, read-only, meaning it could read every row and change none. The weak link it found is the same question my homework post ended on: who WROTE it down? In three of the four ways a row gets written, the AI writes it...including the rows that say I caught it 🙄 So "I caught it" was mostly the AI's word. It's getting better (rows with my actual words went from 0 of 27 in June to 35 of 43 in October), but a catch nobody logs doesn't exist. Between 13 June and 27 August my AI told me an idea of mine was new 208 times. The register has one row about it lol.
So what's the ledger good for? It's where the fixes come from:
- Wrong diagnosis was the top miss type in July, and the AI had caught almost none of its own. Now it's a forced check: before the AI asserts a diagnosis, it names what would prove it wrong and reads that first.
- A miss that came back (logged as a repeat) became a standing rule on which calls the AI makes and which come to me.
- The two biggest miss types each got their own test.
- Three misses in September got past the guard that makes the AI read before it claims. So now the guard checks the repo too.
What's next: rows that say I caught it carry my words, or something the AI didn't write, like the transcript. A record of what was in front of me first, so what got past ME gets counted too. And planted items or an outside check, for my rate.
Same caveat as always: one practice, and the auditor is the same model family as the team it audited 😁
If the human is the check, somebody has to check the human...and it can't be the thing being checked 🤷♂️
The paper: wolfberg.ai/papers/who-caught-it/
Sources
- Never let your AI grade its own homework, the post this one builds on
- The register: every logged miss and who caught it
- Nobody Else Has Done This, the companion note on novelty assertions
- Anthropic: auto mode is now the default in Claude Code (the 1,053-tester study), 7 August 2026 claude.com
- Habituation at the gate: rising approval in human review of AI agent code (Yu et al., 2026) arxiv.org
- AI agents push humans out of the loop (Mitchell, Ghosh and Passi, 2026) arxiv.org