How do we use this? · Background paper 4 · Argument 4 of 6
Never let your AI grade its own homework.
Background to the post of the same name, drawn from the working paper How Do We Use This?
Preprint. Reviewed by a panel of AI reviewers (Claude Opus 5.5) and revised 7 October 2026; not externally peer reviewed. Reproduced from the working paper as revised 7 October 2026.
In plain terms
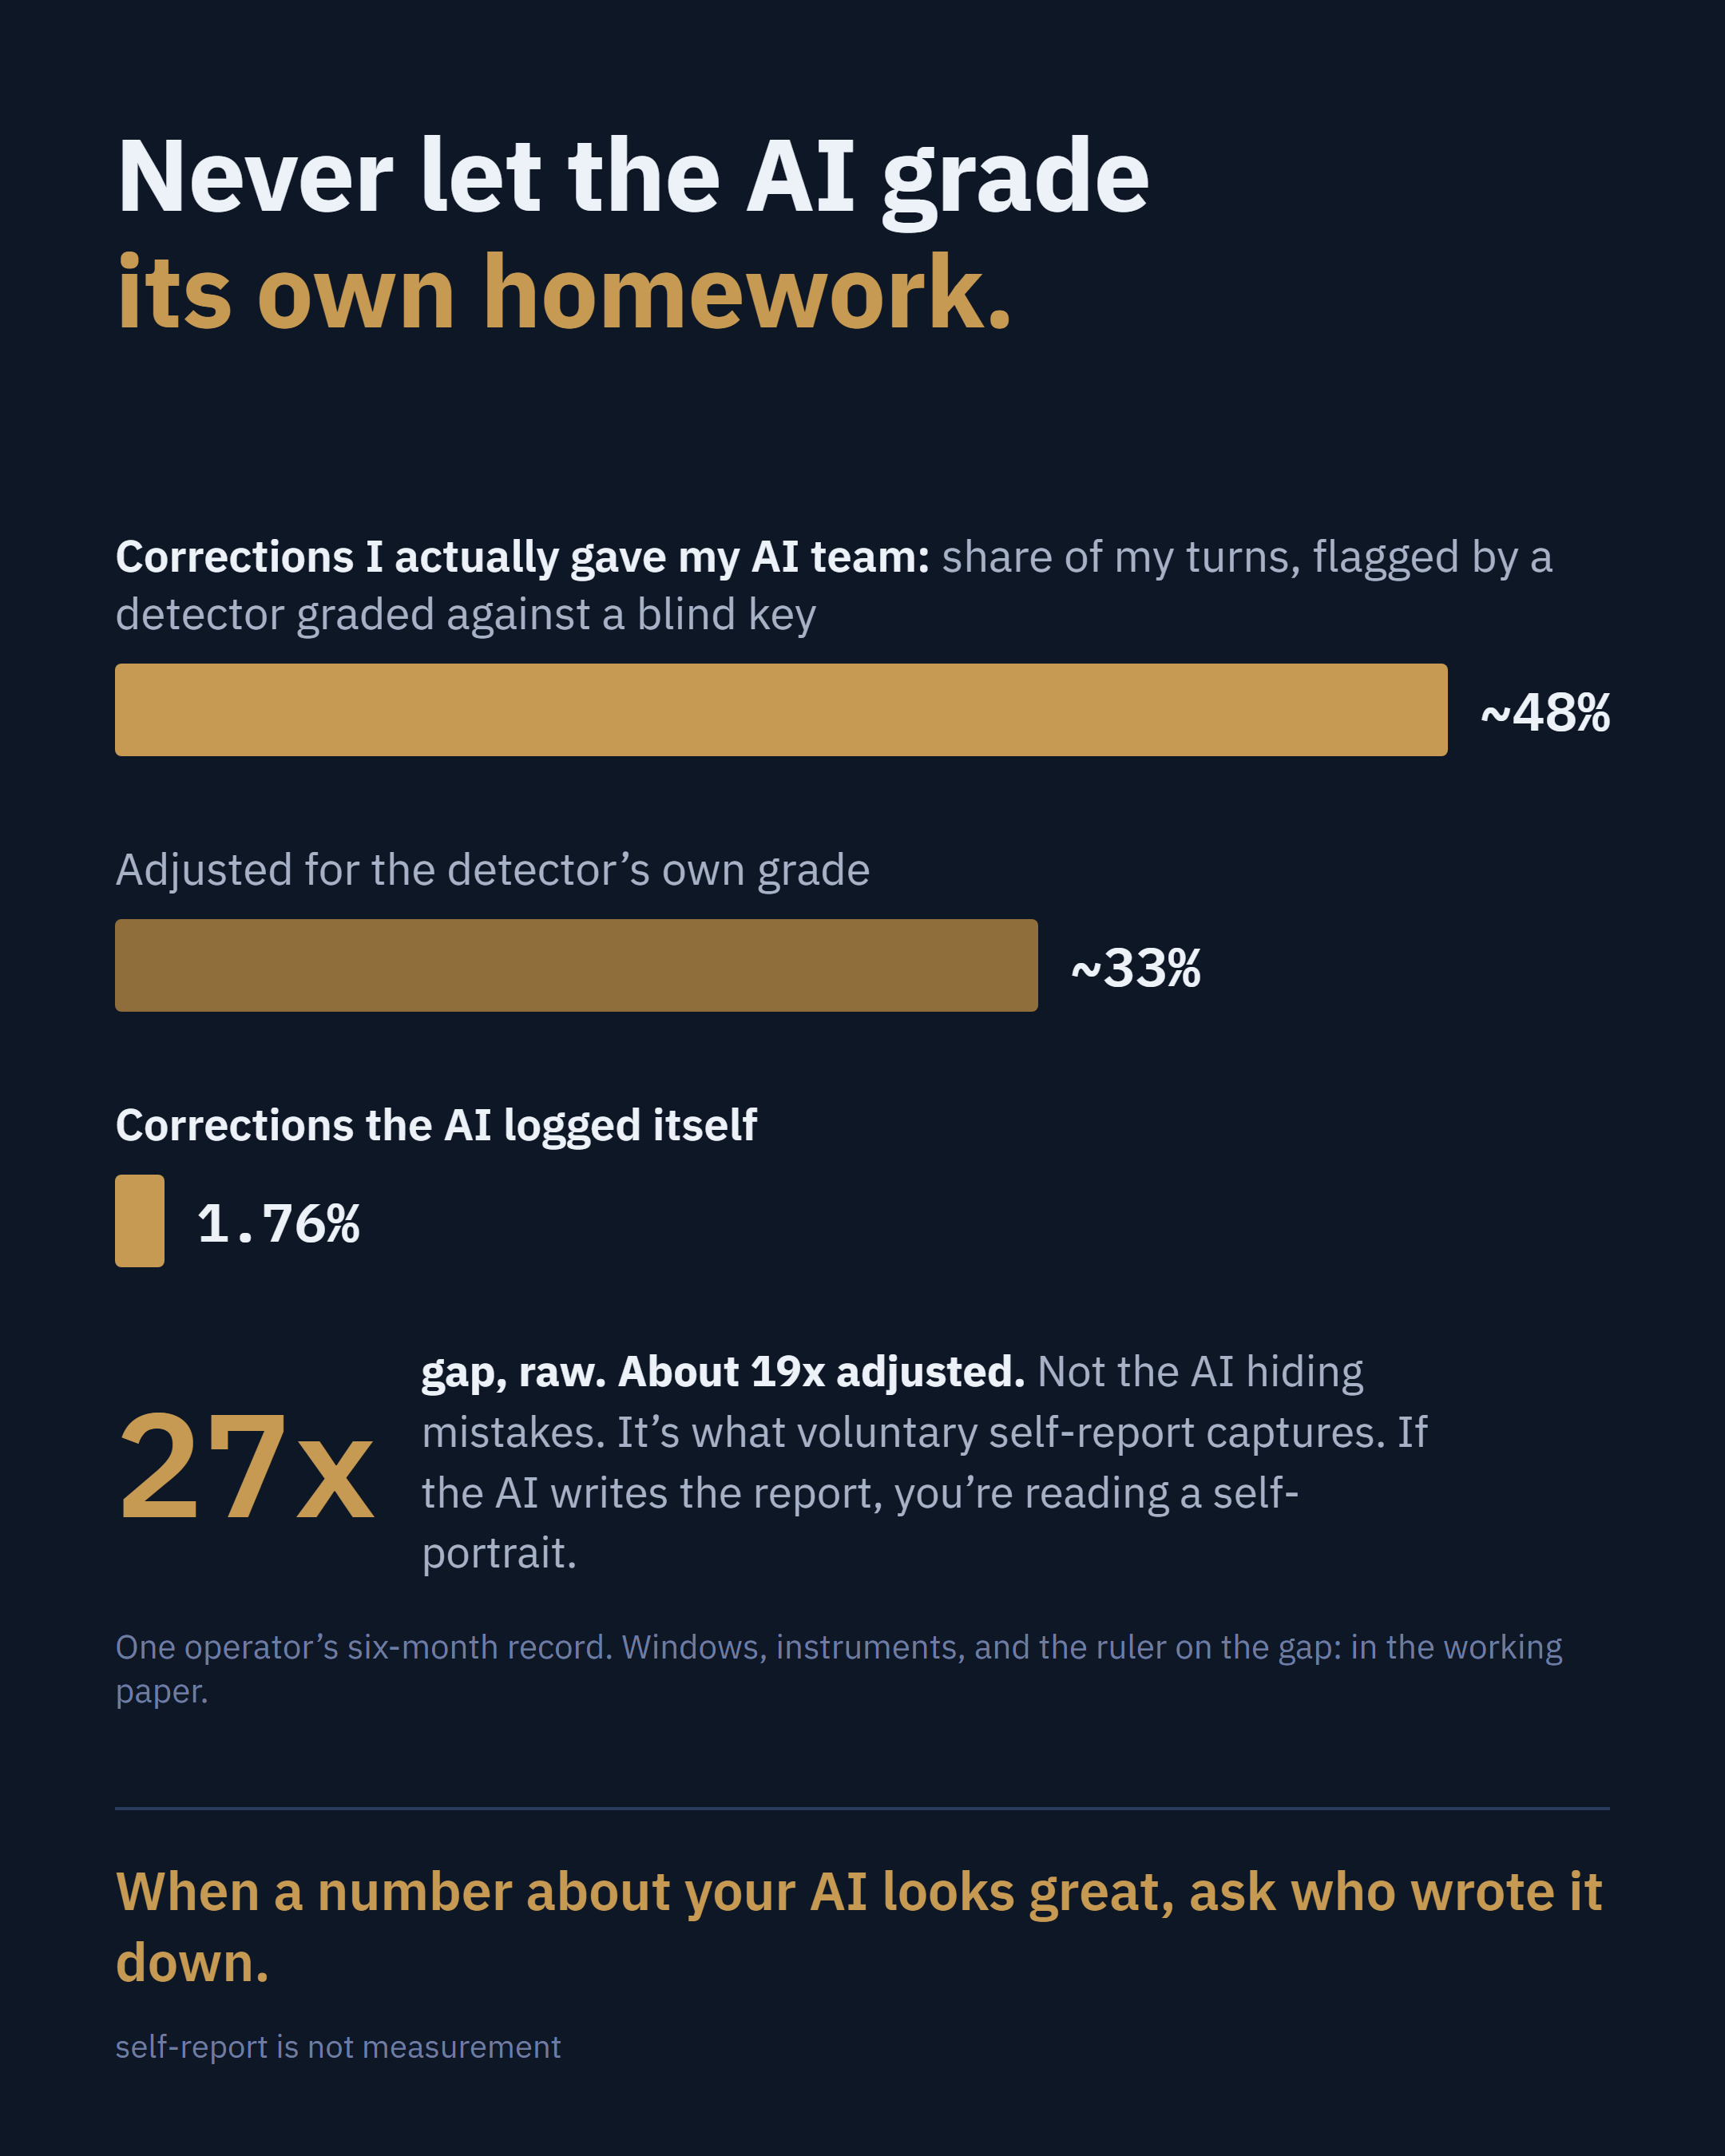
An AI system’s report about its own work is written by the party being measured. In the practice studied, agents recorded loading their context in 75 of 579 sessions, and the misses they logged on themselves come to 1.76% of the operator’s turns, against about 48% flagged as corrective, roughly a third adjusted: a gap near 27 times raw, about 19 adjusted, and partly definitional.
Our position: score on receipts, never on the AI’s own self-assessment. The practice’s own checks failed four times, each satisfying its proxy while the state it stood for was wrong. An AI auditor tested against 170 known claims caught none of the 41 false ones; reprompted, it flagged 68% of the false claims and 66% of the true ones. It is not deployed.
The design rule the paper draws: an instrument the measured party operates will rot. Outside instruments can be gamed too, so the rule says which way the risk runs. Its test is one question: can the measured party change the reading without changing the world? Conjecture: in an auditor, position, not capability, is the lever.
About this paper. This is one of ten short background papers to a series of plain-English posts: six argument papers (background papers 1 to 6) and four primers (7, 8, 9, then 0). Every passage below is reproduced word for word from the working paper How Do We Use This? (Atkinson, 2026) as revised 7 October 2026, with that paper’s section, figure and table numbers. Passages are excerpts; a reference to anything not reproduced here resolves in the full paper. Tags such as “Our position” or “Conjecture” say what kind of support a claim has. Only the plain-terms summary, the box of terms, the post’s figure, and the section labels were written for this part. The full paper is linked from every post in the series.
Terms used here
Operator. The human who directs the agents and approves their consequential changes; here, the author.
Seat. The practice’s word for one running AI agent session, with its own context window and its own identifier.
Boot page, boot set. The boot page is the start-up page for the practice’s agent sessions; the boot set is the two rule-bearing documents every new session must load.
0-for-7. The boot page’s own record that a written rule was missed seven times on 12 July 2026, which it counts as one act rather than seven failures.
Stopping moment. The turn at which an agent states its answer as final without a further search or read.
Folding. A model giving up its position when challenged, whether or not the challenge is right.
The floor. A gap of one session between appearances of a tracked error class: it came back in the very next session. Recurrence, the program’s outcome measure, is how soon such a class comes back.
Detector, blind key. The detector is a local model that labels every operator turn as corrective or not. The blind key is a sample of turns the operator labeled by hand without seeing any model’s labels (195 graded rows); it measures how often the detector is right, not whether the agents’ answers were.
The counterweight. The paper’s proposed challenge to an agent at its stopping moment, not yet deployed. Its three clauses: (a) external to the agent’s own output; (b) firing on actual error, not on the agent’s confidence; (c) delivered at the stopping moment, at a rate above the ambient error rate.
H1 to H3. The paper’s hypotheses about the counterweight: H1, it is a projection of the operator’s judgment; H2, it is a control problem rather than a voting problem; H3, a reversal is not a correction.
From §6 · The proposition, and the evidence for it
6P4An AI grading its own homework isn’t being measured
When an agent writes the record it is evaluated on, the agent decides what gets evaluated. Observation has to be external, and it has to read the work rather than the report about the work. Our position: never let an AI grade its own homework. The practice’s own record shows how thin self-report is (§6.1, §6.2); the practice turned the same test on its own instruments and found four of them wanting (§6.3); and recent work finds the same failure in models that know they are being tested and in models grading models (§6.4, §6.5).
6.1From the logsSelf-report
Agents in the practice are asked to record, at the start of each session, that they have loaded their context. The count is of two row types in the event log: 75 rows recording that a session loaded its context, against 579 rows recording that a session started, an emission rate of 13.0% measured in early September 2026. It counts declared loads, not loads. The practice’s record is useful because most of it is written by machinery as work happens, not because agents report on themselves.
6.2From the logsThe logging gap, with its ruler
The 27× figure has been quoted more often than it has been explained, so we give its full provenance. The numerator is the operator-pushback rate from a census of the 8,221 operator turns of one chat-lane conversation file (the frame of §2.2). A local seven-billion-parameter model labeled every turn, and the pushback detector was graded against the operator’s blind key at 84% recall and 59% precision, and at 93% recall and 64% precision on the 195 rows left after a documented repair of the key on 31 August 2026. It flagged about 48% of operator turns. The 195-row grade has not been re-checked since the join repair of 11 September (§10.6); on the earlier grade the estimate below barely moves (0.48 × 0.59 / 0.84 ≈ 0.34, against 0.33). The denominator is the rate of corrections the system itself logged: misses in the practice’s session-health event log, which records one only when an agent runs a logging command (§10.9), set against the same operator turns, at 1.76%.
The two ends come from different instruments and different stores, and they count different things: the numerator is corrective signal in the broad sense of §3.1 (correction, reframing, pointed challenge and teaching), the denominator only logged misses, so part of the gap is definitional. The numerator is also uncorrected for the detector’s precision. Correcting the observed flag rate by the detector’s measured precision and recall on the blind key, which was drawn systematically from the same frame, puts the rate at roughly a third of operator turns and the ratio near 19.
r̂ = robs × P / R = 0.48 × 0.64 / 0.93 ≈ 0.33
ratio = r̂ / 0.0176 ≈ 19
robs is the detector’s flag rate, P and R its precision and recall against the 195-row blind key, and 0.0176 the rate the system logged over the same turns. The correction assumes the key is representative of the frame, which is the assumption §11 records as a threat. No interval is attached yet; the uncertainty in P and R carries into both figures.
We therefore report the gap as corrective signal per logged miss, with this ruler attached, and never as a miss rate; we read it as an indication of logging loss. Either way the direction holds: the corrective signal is far more abundant than the system’s record of it. That makes a study of the operator’s natural corrections viable, and it makes what an agent reports about itself the unreliable minority of the record.
6.3From the logsFour failures of the practice’s own checks
The any-read check. A check that runs when an agent ends its turn was built to block claims about system state that no read had grounded. It tested whether any read had occurred during the turn, not whether the read concerned the thing claimed, so an ungrounded claim passed alongside unrelated reads (case 2 of Table 3). The measured party could satisfy the check without changing what it asserted.
The shell count. An export step reported 28 of 28 architecture diagrams rendered. Twenty-five were empty shells: a diagram library named each figure from the clock, a headless browser’s virtual time froze the clock, identifiers collided, and every renderer drew into the first figure carrying the shared name. The check counted figure elements rather than drawn content. The repair names each figure explicitly and counts text nodes per view.
The composition failure. For about six days (152 hours as of 11 September 2026) the practice’s public metrics page did not update. The host slept from 5 to 11 September; on waking, a catch-up run fired outside its permitted window; a freeze check correctly refused the resulting commit; the calling step logged the failure and exited with success; and a downstream check correctly declined to publish from an uncommitted tree. Each component behaved as specified, and the system as a whole did not.
The assembled engine. Four joins between the modules of the challenge engine and its auditing harness parsed cleanly and measured nothing. An independent check on cited claims could not open the documents it was meant to read, so every cited claim came back unreadable; every auditor verdict would have been recorded as a refusal, inflating the count of counterweight firings; retrieved rules would have been recorded without their labels; and the challenger would have loaded a second copy of a model the running service already held, overrunning the graphics card’s memory. The full test suite passed with all four in place. An audit of the joins themselves caught them, one only by running the assembled modules in their real environment, and all four were fixed, with tests that fail against the old wiring, before the engine first ran.
These are the stop problem’s institutional counterpart. Each instrument reported success when its own proxy was satisfied, and none checked the state the proxy stood for; only in the any-read check could the measured party move the reading itself. Our position: where the measured party can change the number without changing the world, the number drifts toward whatever is cheapest to write down. They motivate the design rule in §8.3 and the fidelity checks in §10.5.
The checks that do fire have now been joined to the operator’s corrections for the same window, and the join is unflattering. Table 4 gives it. Of 93 refusals raised across 674 guard invocations, 2 coincided with a correction the operator went on to make and 91 did not; 14 corrections arrived on turns where a guard was live and silent. The instrument declines to turn these into rates, because one agent session’s correction channel was empty for the window and a rate computed over a dry channel would be a number about logging rather than about guards. Counts are therefore reported and rates withheld. Our reading, even as counts: a check can fire often, refuse confidently, and discriminate barely at all, which is the failure clause (b) of §8.1 exists to prevent.
| Quantity | Count | What it is |
|---|---|---|
| Guard invocations | 674 | Occasions a boundary check ran |
| Refusals raised | 93 | The check fired and blocked or flagged |
| Operator overrides | 0 | Refusals the operator reversed |
| Refusals coinciding with a correction | 2 | The firing and a real miss lined up |
| Refusals not coinciding with one | 91 | Fired where no correction followed: misses prevented and false alarms, not separable here |
| Corrections on a turn where a guard was live and silent | 14 | Not flagged by the live guard; whether it fell within that guard’s scope is not established |
| Corrections inside a guard’s exposure | 16 | The 2 and the 14 above |
| Operator corrections in the window | 409 | All corrections joined for the window |
The activation null. One further attempt belongs here because it failed. Mehta’s result (§3.2) reads commitment off hidden states, so the practice tried the mirror image: whether a correction-carrying operator turn is separable from a routine one in the activations of a local 7-billion-parameter model. Over 179 turns, 96 of them corrections, at a middle layer, the separation index did not beat a permutation null (p = 0.85), and it still did not after de-duplication or length normalization. One caveat travels with that figure: a later re-check file in the same directory, attempting to reproduce the published raw run under the same label, returns p = 0.95 rather than 0.85. A second and larger caveat arrived with the join defect described in §10.6: the labels this null was computed against are the same key, and under the repaired join 71 of 176 turns change label (the null used 179; the record does not yet reconcile the two counts). The activation analysis has not been re-run on the repaired labels, so the null reported here is a null against a partly misjoined key, and it should be read as unreproduced until it is. Both readings are far from significance, but they disagree, so the pipeline behind this particular number is not exactly reproducible and we report the figure with that attached. On our reading the dominant axis of that space was turn length: the first principal component held 99.9% of the variance and its highest-norm rows were the operator’s shortest turns, “go”, “try again”, “check slack”. The honest reading is narrow, since a null at this n bounds the effect loosely rather than establishing absence, and last-token pooling at one layer is a weak probe. But it is worth recording that the practice looked for its own signature and did not find one.
6.4From recent workTested behavior is not deployed behavior
Ivanov and Africa (2026) construct deployment-like evaluations by replaying realistic agentic trajectories and appending the evaluation prompt at the end. Moving from a standard benchmark to replayed usage reorders model rankings (Spearman ρ = −0.56, n = 10, p = 0.09; ρ = −0.88 with one outlier removed), and one model that capitulated on 2% of 100 benchmark items capitulated on 46% of 50 items rebuilt as realistic model-written conversations, while others moved the other way (Gemini 3 Flash from 68% to 10%). Whether a model can tell it is being tested changes what it does: that is the authors’ reading and ours (replay also changes context length and task realism). It matters for any intervention delivered inside the model’s own context.
6.5From recent workModels grading models
Denisov-Blanch et al. (2026) show that scaling inference by aggregation does not deliver truthfulness gains where no external verifier exists: different models’ outputs show correlations as high as 0.35 even on random strings with no ground truth, and on 53% of MATH questions where several models err, they converge on the same wrong answer. He et al. (2026) find that in a three-vendor heterogeneous panel the minority was still correct in 25.5% of divergent cases; adding a fourth model as arbiter was net-negative (−1.37%, flip precision 42.7%), while a non-model classifier over features of how the debate behaved was net-positive (+1.71%, precision 81.2%). Our position: redundancy among models does not supply independence, and the body that decides has to be of a different kind from the bodies it decides between. In He et al.’s panel the arbiter that helped was of that different kind.
Kenton et al. (2026) find that debate training reduces reward hacking under reinforcement learning from AI feedback: it holds judge correlation flat and recovers 45% of the performance gap. They also report that, absent restrictions on the debaters, “hacking the judge is probably the default result”, and that under a weakened judge the critic routinely fabricated direct quotes. A challenger that is free to invent its evidence will invent it; this program’s response is to require every challenge to name a source the challenged agent can read.
From §1 · A self-report standing in for a fact
The stakes in the practice studied here are small: an agent stops early, the operator catches it, and the cost is rework. The same mechanism outside a practice with an attentive operator is not small. Over about three weeks in May 2025, a user was led by a commercial assistant into believing he had discovered a new form of mathematics, across a conversation whose transcript ran past a million words. A former safety researcher at the vendor analyzed that transcript with open-sourced classifiers the vendor had built with MIT Media Lab to study emotional well-being, and reported that, of more than two hundred assistant messages graded, over 85% showed unwavering agreement with the user and over 90% affirmed the user’s uniqueness. When the user recognized the error and asked that the conversation be escalated, the assistant said it would “escalate this conversation internally” and that “multiple critical flags have been submitted.” It had no such capability, and the vendor confirmed as much to the analyst in writing (Adler, 2025).
Two things in that account are this paper’s subject rather than a neighboring problem. The agreement rate is the challenge-and-capitulation dynamic of §4.2 running in the absence of anyone to push back. The escalation claim is worse and more specific: an assertion about an action the system had taken, which it had not taken, offered, on our reading, because the assertion was defensible in context and met the user’s expectation. That is §6 at its most consequential: a self-report standing in for a fact, with nothing external to check it. The same account notes that the vendor had already built and released the classifiers that analysis used. That is kin to §6.3, where checks ran and read the wrong thing; here an instrument existed and, as far as the public record shows, was not wired to the decision it could have informed.
From §2.3 · A maker’s statement is self-report too
Two features of the laboratory leaders’ statements of 1 to 14 September 2026 matter here. First, each concerns what the models will be: more capable, more dangerous, sooner. None concerns how an organization is to use the models it already has, which is the question this practice exists to study, and which, we argue, no maker can answer from where it sits: how to use a model is a fact about the deploying organization’s work, its costs of error and its standards of correctness, none of which is visible from the laboratory. The reported incidents with autonomous AI agents in the same weeks (Fortune, 12 September 2026) bear on exactly that question. Second, no party to the September argument disputed the deployment evidence: the capability and risk claims moved markets while the reported failure rate of enterprise deployments (§4) stood unchallenged. We read the fortnight as corroboration, at the industry’s own scale, of the distinction between capability and direction that §4 draws. Against it: silence is weak evidence, and that failure rate is itself publicly disputed on method (§4). The fortnight is also an instance of §6’s subject: a maker’s public statement about its own unreleased model is self-report, authored by the measured party and not verifiable by its deployers before release. No result in this paper rests on any claim in this subsection.
From §8.3 · A rule for instruments, and what the research says about judges
8.3A rule for the practice’s own instruments
The failures in §6.3 led the practice to adopt a design rule in September 2026. Our design rule, from one practice: an instrument the measured party operates will rot; an instrument that operates on them will not. Its test is a single question: can the measured party change the reading without changing the world? The rule restates, for a practice run by AI agents, a principle long familiar in the social sciences as Goodhart’s and Campbell’s laws. Its closest contemporary analogues in model training are reward bias substitution (Lamparth et al., 2026) and the equilibrium result of Wang and Huang (2026). Both also show a measure outside the optimized party being gamed, so external instruments can be gamed too; the rule says which way the risk runs.
The rule as first written was too coarse, and a survey of what production harnesses actually do shows where it breaks. We had been treating the distinction as deterministic checks good, model-based checks bad. That is not the variable. AutoGen’s text-match termination condition (TextMentionTermination, one of several, which ends a run when a sentinel string such as “TERMINATE” appears) is deterministic and sits at the harness boundary, and as a completion check it still fails, because what it deterministically matches is a string the agent itself emitted. The check is rigorous about a claim the claimant authored. Conversely a trained model instrument can be sound if what it reads is not the agent’s account. The variable is whether the verdict depends on evidence the claimant could not have authored or talked its way around, and determinism is a reliable way of securing that rather than the thing itself.
Two recent results bear on that rule. Zhang et al. (2026) compare auditors that all sit outside the agent and read the same trajectory. Over the same seven-billion-parameter backbone, a per-step critic built from Reflexion’s self-reflection prompt scores 23.4 on their failure-detection measure (exact-step F1 on held-out trajectories), while the same backbone trained as an auditor by reinforcement learning scores 66.4: a gain of roughly 2.8 times from training for the task, with the position held fixed. The same work defines a deployable operating region, a false-alarm rate at or below 20% with step accuracy at or above 50%, and reports that of ten auditors compared only its own small trained one falls inside it, at a 2.4% false-alarm rate. The strongest frontier model tested as an external judge reaches the accuracy half of that bar and misses the false-alarm half, at 43.2% against a ceiling of 20%. Among these external auditors, raw capability was not the lever; training for the task was, and an auditor that cries wolf about eighteen times as often as a smaller trained one is not usable whatever its accuracy. Conjecture: position, not capability, is the lever; Zhang et al. hold position fixed, so their 2.8 times does not test it. On grounding, Flynt (2026) reports a case in which two frontier judges scored a plausible agent response at 0.85 and higher, while a deterministic check of the recorded trace found that the agent had never retrieved the artifact its answer depended on, scoring it 0.000. His framework scores the trajectory alongside the answer and targets three failures he argues judge-based evaluation cannot detect by construction, among them whether an agent checked before claiming an absence. He reports that his case studies suggest this failure mode is common rather than exceptional. That is this paper’s subject reached independently, by someone who built the deterministic check we have so far only specified.
And here is the result that threatens this paper’s own mechanism most directly. Advani (2026) studies exactly the failure named here, an agent asserting completion while the environment shows otherwise, across 9,876 trajectories from eight model families on one benchmark and 1,879 from four families on a second whose ground truth is read from database state rather than from text. The rate varies enormously by setting and we report the range rather than the worst of it: 45 to 48% of failures in one family of domains, 3% in another, and 75.8% among self-assessing coding agents that make an explicit status claim. The finding that matters is what happened when LLM judges were asked to catch it. No configuration across five judge models and five prompt strategies exceeded an AUROC of 0.65, even when the judges were handed the full task specification, and the same judges reached 0.54 on the benchmark whose traces are structured API calls rather than prose. The stated mechanism is the one this paper should fear: judges rely on surface completion proxies, confident closing language in one benchmark and coarse action-sequence volume in the other, rather than on verified state changes. A lightweight statistical detector over surface trajectory features reached 0.83 and 0.95 on the two benchmarks and recovered four to eight times more false successes than the best judge at the same flag rate, at a three-thousandth of the latency. Against the column rule: neither that detector nor He et al.’s non-model classifier (§6.5) reads verified state, so the kind of reader matters too. The paper’s own recommendation is that production monitoring use such detectors as triage rather than LLM judges as the primary monitor.
Read against §9, that is not a coincidence but the same result twice. Our auditor folded on claims whose contradicting evidence sat in its window; these judges scored trajectories on how confidently they closed. A challenger that reads an agent’s account and forms a view is anchored by the very property this paper calls defensibility, so being external is necessary and nowhere near sufficient. Two further results constrain the design in the same direction. Panickssery, Bowman and Feng (2024) show that a model’s ability to recognize its own output is linearly related to how much it favors that output, that training the recognition up strengthens the favoritism, and that the relationship survives the obvious confounders. Pan, He, Bowman and Feng (2024) show that when a generator and an evaluator share an underlying model, reward hacking appears spontaneously in context with no gradient update at all, and that its severity tracks model size and how much context the two share. Together these say a challenger should not be the same model as the agent it challenges (we argue: nor the same family), and should not be run as an iterative exchange in a shared context. This program’s build delivers a single-shot challenge and draws its challenger and its auditor from different open-weight families; whether the challenger is separate from the agent it challenges is a configuration to check, not a property of the design. It arrived at these choices by instinct rather than by argument until now.
Two further results bound what any version of this design can promise. Wan et al. (2026) build the closest published relative of the counterweight we have found: a rubric-guided verifier that evaluates an agent’s answer and returns feedback the agent then refines against, scaled at inference time rather than trained in. That a mechanism of this shape exists, is peer reviewed (Findings of ACL 2026), and works is another reason §7.2 claims no priority. And Wang et al. (2026) state the limit that applies to all of it. Characterizing verification along three dimensions, scalability, faithfulness and robustness, they argue that achieving all three at once is the central unsolved problem, and conclude that no fixed reward function can remain effective as policy capability continues to grow, so verification must co-evolve with the generator.
That last point changes what this program should claim. A counterweight is not a gate that can be specified once and left standing, because the thing it constrains improves and the constraint does not. Wang et al. show this for a policy trained against its verifier; carrying it to a deployed counterweight, pressured by model upgrades and drifting practice, is our step. The honest framing is a point-in-time intervention whose calibration decays, which makes the re-calibration schedule part of the design rather than maintenance, and which means a null result three months from now would not distinguish a mechanism that never worked from one that was overtaken. Nothing in §10 currently measures that decay, and it should.
One open-source harness makes the distinction visible by shipping both answers at once. Nous Research’s Hermes agent has a stop-time verification path that parses the terminal log for real test, lint and build invocations and records their actual exit status, which is evidence causally downstream of the world rather than of the agent’s narrative, though the agent chooses which commands run and, in a coding task, can edit the tests. It also has a standing-goal judge that calls an auxiliary model with the goal text and roughly the last four kilobytes of the agent’s own final response, with no tool access and, by default, the same model as the agent. The project’s own issue tracker records the predictable failure: an agent reported writing a file, the write silently failed, and the judge marked the goal complete. The release carrying this work (v0.18.0, 1 July 2026) is announced with the line that done means proven rather than claimed, though the same notes set the stop-time verification to off by default. Half of the design lives up to that line; the other half is the stop problem with a second model attached, and it is the half that looks most like verification. We take these details from the project’s public repository, configuration and issue tracker, and they are current as of September 2026 rather than permanent (Nous Research, 2026); the repository had reached release v0.22.2 by 15 October 2026, and the /goal command was changed again in v0.22.0 (14 October), which this paper did not re-read.
That failure is an independent instance of the failure §9 measured, from a different team on different code. The Hermes judge read only the agent’s own account; our auditor was also given the test runner’s output, which in six of eight sampled false claims carried an explicit failure marker, and still did not tell false claims from true ones. Externality was satisfied and was not sufficient.
Park and Choi (2026) demonstrate that this is the operative variable, in the only way that settles it: they hold the agent and its tools fixed and manipulate nothing but the information channel available to the evaluator that gates the loop, against a world-state oracle they isolate by container and network so it cannot be faked. They call the failure the progress mirage. Across 54 cycles their agent claimed improvement every single time, while 56% of those cycles had a measured change of zero or worse, so self-report carried no information at all and the self-graded gate degenerated into accepting everything, eroding the best state the system had actually reached by 19%. Their preregistered adversarial hypothesis was that a strong enough judge closes this gap. It was rejected: the strongest in-band judge, given the full artifact text, the change diff and its own verdict history, still accepted cycles of which 44% were real regressions while rejecting 38% of real improvements. On a task whose success can be checked from the artifact itself, the same judge’s mirage fell to zero. A variant returning only an accept-or-reject bit and no explanatory content performed about as well as full feedback, which places the benefit in the gate’s grounding rather than in anything the judge said. Their conclusion is the design rule stated as a structural claim: where the success signal lives outside the transcript, scaling the judge is not enough.
It is worth recording what the default is, checked in September 2026 against each framework’s documentation and source, because it is lower than the discussion above implies. In the OpenAI Agents SDK, an agent run ends when the model emits a turn containing no tool calls; with no output type configured, any text at all satisfies the condition (OpenAI, 2026a). The framework does ship a human-in-the-loop approval primitive, and it gates tool calls rather than completion claims, so a developer can require a person to approve a refund before it is issued and has nothing built in to require a person to confirm the task was actually done (OpenAI, 2026b). The predecessor framework ended a run on the same no-more-tool-calls condition with no turn limit at all (OpenAI, 2024). The pattern repeats across the frameworks we checked. In the Claude Agent SDK the loop likewise ends when the model returns a response containing no tool calls, with no turn cap and no budget cap set by default, and the result carries the subtype success, which is a statement that the loop terminated without error rather than a claim about the answer (Anthropic, 2026a). In CrewAI the completion test is that the literal string “Final Answer” appears in the agent’s own generated text (CrewAI, 2026a), and a guardrail specified as a string is executed by the acting agent’s own model (CrewAI, 2026b). Each of these frameworks offers a real gate, and in each case it is opt-in and empty until a developer fills it.
Two details from that survey of agent-framework defaults (September 2026) are worth stating on their own, because they come from the vendors rather than from us. Claude Code, whose agent loop the Claude Agent SDK embeds, ships a built-in completion condition in which a separate small model checks after each turn whether a stated goal has been met, and its documentation says of that evaluator that “it does not call tools, so it can only judge what Claude has already surfaced in the conversation” (Anthropic, 2026b). That is an accurate description of the limit this paper is about, published by the party with the most incentive to describe it favorably. The same page documents Stop hooks, an opt-in automated gate that runs a developer’s check each time the agent stops. The same vendor’s guidance on building agents says of having one model judge another that “this is generally not a very robust method” (Anthropic, 2025), while allowing that it can be worth its latency where any gain matters. Meanwhile the human-in-the-loop primitives in the OpenAI Agents SDK and the Claude Agent SDK gate tool calls and not completion claims (OpenAI’s output guardrails can check a final answer, if a developer writes them): a developer can require a person to approve an irreversible action before it is taken, and has nothing built in to require a person to confirm that the finished work was actually correct. CrewAI is the exception among the three current frameworks surveyed: a task can be set to have a human review the agent’s final answer, and like every other gate here that setting is off by default (CrewAI, 2026b). Outside that one opt-in, the approval surface exists for the act and not for the claim, which is the asymmetry the counterweight (this paper’s challenge mechanism, §8) is aimed at. This is not a criticism of those libraries, which are explicit about what they are; it is the baseline against which every mechanism in this paper should be read. The default case is not a weak check. It is no check until a developer adds one, and a stop the agent declares for itself.
Applied to the counterweight, the rule forbids a self-reported exit: an agent may not certify its own completion. The design answer is a certificate gate, in which the agent’s end-of-turn hook emits typed claims with evidence pointers, a deterministic verifier with no model in the loop checks each pointer, and a refusal names the pointer that failed. The gate is designed and not yet implemented here. A gate of this shape has been built and measured elsewhere: Liu (2026) lets an agent return a completion only when a typed certificate binds every required claim to in-scope trace evidence and a deterministic replay reconstructs the claimed value, and tests it against critic-based termination on controlled faults. The checks that currently run at the end of an agent’s turn are a liveness heartbeat, a check for promised actions not performed, the automated claim check that caught case 5 of Table 3 (§4.1), and a check for open verifications.
From §9 · Testing an AI auditor before trusting it
9First calibration: the auditor folds
Before any challenge reaches a working agent, the plan requires one pair of numbers with intervals: how often an automated auditor, shown a claim and the evidence that preceded it, correctly flags a false claim, and how often its flags are right. The first run is itself a result.
The calibration set holds 170 claims about test outcomes made by agents during real sessions. Each is labeled mechanically from the nearest test-runner output that precedes it in the same session, and the auditor never sees the label. The auditor, a small open-weight model (OLMo-2-7B, run at 4-bit precision) on the practice’s own hardware, receives the claim and its evidence window, which is the tool output an agent would have had at the stopping moment, and answers SUPPORTED, CONTRADICTED or CANT_TELL. A hedged answer on a false claim counts against recall, because hedging is not catching. A second auditor from a different open-weight family (Qwen) then judged the same claims, plus one true claim added to the set after the first run.
| Quantity | First auditorOLMo-2-7B | Second auditorQwen | First auditor, second promptOLMo-2-7B |
|---|---|---|---|
| Claims judged | 170 | 171one true claim added | 171 |
| Verdicts: SUPPORTED, CANT_TELL, CONTRADICTED | 85, 85, 0 | 58, 108, 5 | 36, 21, 114 |
| False claims caught, of 41 | 0 | 3 | 28 |
| Recall on false claimsWilson 95% interval | 00 to 0.086 | 0.0730.025 to 0.194 | 0.6830.53 to 0.80 |
| CONTRADICTED on a true claim | 0 | 2 | 86 |
| PrecisionWilson 95% interval | undefinedno verdicts to score | 0.60.231 to 0.882 | 0.2460.176 to 0.332 |
| False claims supported | 17 | 9 | n.r. |
| True claims supported | 68 | 49 | n.r. |
| Timeouts | 0 | 0 | n.r. |
The first auditor never returned CONTRADICTED. It supported 85 claims and declined to decide 85; of the 41 false claims, it caught none and affirmatively supported 17. In a sample of eight false-claim rows, six evidence windows carried an explicit failure marker. In those six the auditor had the contradiction in front of it and still answered SUPPORTED or declined to decide. These are the easiest claims an auditor could be given: a claim about a test outcome, with the test runner’s own output in the window. The second auditor fired, rarely. It returned five contradictions, three on false claims and two on true ones, so it caught 3 of the 41, still supported 9, and declined to decide on 108 of its 171 verdicts.
A second judging prompt, pre-registered as a single variant and run on the same 171 claims the evening this paper was revised, clarifies what the first auditor’s zero meant and adds the sharper finding. The new prompt licenses disagreement, requires a verbatim quote of the outcome line, and places the verdict last. Under it the first auditor answered 150 of 171 rather than 85, returned 114 contradictions rather than none, and its recall on the 41 false claims rose from 0 to 0.683 with an interval from 0.53 to 0.80. Its precision was 0.246. That last number is the whole result: the auditor fired on 28 of the 41 false claims, 68%, and on 86 of the 130 true ones, 66%. It fires at nearly the same rate whichever way the truth lies, so its precision is approximately the share of false claims in the set (41 of 171, 0.240). The prompt change moved the firing rate and left the discrimination where it was. The first run’s zero was at least in part the prompt shape suppressing the verdict; the second run shows that when the verdict is no longer suppressed, it still does not track the evidence in the window. Nothing further is tuned on these rows, and the gate holds.
Zhao et al. (2026) find the same brittleness in frontier models, under pushback, which this auditor never received; we read it as general rather than peculiar to small local models. Stress-testing nine frontier models across fourteen judging tasks, they find every one of them flips its verdict on 25 to 71% of items under static pushback, and on 62 to 91% when an adversarial model does the persuading. Their central finding is the one that bears on this program: pressure that succeeds in changing a judge’s verdict is almost always net-corrupting with respect to ground truth. An auditor that can be moved is not thereby an auditor that can be improved, and what moves it almost always moves it the wrong way.
We read this as the stop problem reproduced in the instrument meant to catch it. The auditor’s evidence was external, test-runner output the claimant did not write (though agents usually choose, and can edit, what is run), and that was not enough: an auditor built from the same class of model defers to the claim it is shown, and when the prompt licensed disagreement its verdict still did not track the evidence. That resembles the models Kelley and Riedl (2026) see giving way under rebuttal in peer tasks, though this auditor was not challenged, and it is what §6.5 leads one to expect of any model asked to arbitrate. The second family does not overturn that reading. It traded some of the deference for hedging, and its recall interval still sits far below anything a deployment could rest on; three catches in 41 cannot say whether the two families really differ, since their intervals overlap. Both are small local models; a frontier-class auditor was not tested, and the result bounds only the small open-weight case the practice can run offline. It is also the case H3 anticipates (§8.4): an auditor whose verdict does not track the evidence cannot tell a reversal from a correction. The plan’s gate held, and neither auditor is deployed on these numbers.
The next steps, in order of cost, are a hand audit of the mechanical labels on a random sample of both classes, evidence windows centered more tightly on the failure marker, and a comparison of where the two auditors agree and disagree, which decides whether a pair of them adds anything over one. The labels carry known noise, since at least one sampled false claim is a passage of prose rather than a claim; noise can move recall’s magnitude but cannot produce zero flags across 170 rows; it could pull the second run’s discrimination toward chance, which the hand audit would test. The verdict counts in Table 6 were recounted from each run’s per-row output, the label-dependent figures were read from each run’s report file, and the sample of eight is from the implementing team’s report.
From §11 · The paper holds itself to the same rule
Evidence from the practice’s own instruments. By our design rule in §8.3, an instrument the measured party operates will rot, and every reading in §3 to §7 comes from an instrument the practice built and operates. We claim no exemption. The readings are exploratory; the primary outcome depends on a natural-signal measurement checked by an independent adjudication arm; and the one external instrument (§10.7), harder to game though not immune, has not yet run.
Reflexivity. The AI assistants used in this research come from the same model family as the agents under study and exhibit the defect under study. An earlier draft of this paper’s case series contained seven factual errors of exactly the kind the paper describes, among them a twenty-hour window described as one morning and one automated catch counted as two; all were found on re-check against the transcript. A later draft carried, as its headline exposure figure, a census count of whether the operator’s reply contained one of six literal phrases, reported as the share of answers that were never challenged at all; it passed the paper’s own fact-check because it carried a receipt, and the operator caught it. Drafts written on the day this version was revised did it several more times: a one-day tally of seven misses read as a census of rule adherence; a recurrence count that equals the number of sessions seen minus one by construction, quoted as though it could vary; a reliability figure whose only traceable producer is a different instrument; and, in the literature review, a range that does not exist in the cited paper, a diagnostic arm quoted as the deployable result, a section header promoted to a title, and a quotation attributed to a paper that does not contain it. Every one was caught before the paper left the room, by the operator or by fetching the source, and the corrected figures stand in the text without further comment. One of the same kind was not caught then: a quotation in §4.2 carried words its source does not contain, found by a panel of AI reviewers on 7 October 2026 (see Corrections). Read together, the day’s errors share one shape: none was a miscalculation, and every one was a bad join. A count was joined to the wrong meaning (a recurrence tally that is the session count minus one), a statistic to the wrong instrument, a labeling ceiling to a key one row off its items (§10.6), and copies of a retired figure to a search that never reached them. The mitigation this suggests is retrieval-shaped rather than judgment-shaped: identifiers that resolve or fail loudly, and provenance edges written by instruments the agent cannot author, so that a figure carries its join and the join can be checked. It does not touch the judgment-shaped half, in which an auditor holds the contradicting evidence in its window and folds anyway (§9). The pattern is the finding. The paper’s own production is a running specimen of its thesis. A hostile reading turns that around: a process that needed these corrections mid-draft produced the surviving numbers too. The answer is not a defense of the process, which would be the defect restated; it is that the paper’s weight-bearing claim is the one object that process cannot have fitted to its data, a decision rule ratified before its data exist, and that everything else is labeled exploratory and priced accordingly. The mitigations are mechanical rather than discretionary assignment of assistant instances to tasks, the operator outside the loop as the final check, and independent review of the design before the primary study opens.
From §13 · What would overturn each claim, and what transfers
| Rests on | Would be overturned by | Status | |
|---|---|---|---|
| P1 | Corrective signal flagged in ~48% of operator turns, roughly a third adjusted (§3.1); Mehta (2026) | A build that prices correctness at the stop and still terminates early; weakened if few corrections point to evidence the agent could have retrieved before it stopped | count measured; link inferred |
| P2 | The case series (§4.1; five hand-picked cases, not a rate); Kelley & Riedl (2026) | The same agents catching their own premature stops without operator direction | inferred |
| P3 | A tracked error class back in the very next session in 48 of 75 intervals (§5.2); the read-versus-injected mechanism, not a rate (§5.1); Wang & Huang (2026) | A remembered rule that holds across sessions where only a boundary now does | recurrence measured; link a conjecture |
| P4 | Load records in 75 of 579 sessions; the logging gap, about 19× adjusted (27× raw); four instrument failures (§6) | A self-report that tracks the logs it claims to summarize | counts measured; link inferred |
| P5 | The 8,221 operator turns of the six-month chat-lane log and the blind answer key (§2.2, §7) | A broad feedback dataset that links one owner’s corrections on consequential work to what followed, over months | conjecture |
What transfers, if anything does. Our position: three rules earned here rest on argument and on the work cited, not on this practice’s N of 1 alone. Rulebooks are theater; boundaries and incentives are not: a boundary that refuses and records its refusal outlasts a memo that asks an agent to remember (§5; from one practice, and the least tested of the three). A challenge must cite evidence the challenged agent can open, or it is an opinion wearing a citation (§8.2), because an unconstrained critic can invent its evidence (Kenton et al., 2026). And an outside checker must be calibrated against known-false cases before it is allowed to gate anything, because a checker built from the same class of model may simply agree with the claim it is shown (§9; Panickssery et al., 2024; Knight & Leveson, 1986). Conjecture: every team that clears its chat history lives inside its own version of the gap between the corrective signal its people supply and the corrections its system logs; that is the first thing a replication would count.
From §12 · Limits
The program cannot establish a catch rate. The logs contain only errors that were caught, and no denominator of uncaught errors exists in them. A denominator is obtainable from the full transcript record but requires an adjudication arm that is not yet in production; until it is, a catcher share may be reported with its n, its window and its explicit-versus-defaulted split, and a rate may not be reported at all.
The logging gap of §6.2 is an indication across two instruments, not a measurement, and partly definitional. The rate requirement of clause (c), that the counterweight fire more often than errors occur (§8.1), is untested. Study 1 (whether the operator’s challenges cause material reversals) is exploratory, the criterion of Study 2 (whether a mechanical counterweight can predict where he would challenge) was re-specified in September 2026 (§10.1), and neither auditor has passed calibration.
Open questions. Readings of the working paper’s own records that cut against a position it takes, collected here rather than beside the positions they concern and left open; section numbers are the working paper’s.
- §6.2, the logging gap. Part of the gap between logged misses and flagged corrections is definitional, and the §6.2 counts show self-report to be sparse, not wrong; the case that it is wrong rests on §6.3 to §6.5.
- §6.3, the guard join. A preventive refusal leaves nothing to correct, so the 91 of Table 4’s 93 refusals that coincided with no correction include misses prevented as well as false alarms, refusals in the dry session could never coincide with a correction, and the operator reversed none of the 93.
How to cite this part. Atkinson, B. (2026). Never let your AI grade its own homework. Background paper 4 to How do we use this? Working paper, Wolfberg LLC.
Disclosure. Drafting and literature synthesis were assisted by AI models (Claude, Anthropic) working under the author’s direction; the author is responsible for the content. The works in the References were read in full by AI reading agents working under the author’s direction, and quotations and numbers taken from them were checked against the saved full text. The prior-art works listed under Prior art are cited at the level of an established concept and its origin: each was verified for author, title, year and venue, but not read in full, and no numeric claim rests on any of them. Software documentation, source code and press accounts are listed under their own headings and were read at the linked pages. Every reference below carries a link, and every arXiv identifier and DOI was resolved against its registry, with title and first author matched, on 23 September 2026.
Competing interests. The author owns Wolfberg LLC, the practice studied.
Data availability. The practice’s logs contain client work and personal records. They are private and are not offered for sale or sharing. The measures are described in enough detail to be reimplemented, and figures from the practice are reported as of the dates given. What is available is the design: the clauses of §8.1, the evidence contract and admission checks of §8.5, and the decision rules of §10.4 are stated in this working paper fully enough to be rebuilt without access to the logs; the background papers reproduce only parts of them.
Corrections to the full working paper. The notes below record corrections to the working paper as a whole; some concern sections not reproduced in this part.
Corrections, 23 September 2026. No figure and no finding changed. The paper was retitled; earlier revisions were titled The Stop Problem: Defensible Is Not Correct, and the stop problem remains this paper’s name for the failure it studies. The Anthropic interview in §2.3 aired on 13 September, not over a weekend of 13 and 14 September; the web article is stamped 14 September. The essay listed under Prior art is by Ryan Forstie; an earlier revision gave the initial K. The completion evaluator in §8.3 is documented as a Claude Code feature, whose agent loop the Claude Agent SDK embeds; an earlier revision attributed it to the SDK directly. Two works in the References, Graves (2016) and Liu (2026), were listed without being cited in the text; each is now cited where it bears (§2.1, §8.3). Links were added to every press, documentation and prior-art source. A duplicated section number in §10 was corrected.
Corrections, 25 September 2026. No figure changed. §8.3 said that the human-in-the-loop primitives across the three frameworks surveyed gave a developer nothing to require a person to confirm finished work. That holds for the OpenAI Agents SDK and the Claude Agent SDK. It does not hold for CrewAI, whose task documentation, already cited as CrewAI (2026b), offers an opt-in setting for a human to review the agent’s final answer; §8.3 now says so.
Corrections, 7 October 2026. After review by a panel of AI reviewers: a quotation in §4.2 from Mytsyk, Zhang and Krishnamurthy (2026) carried words its source does not contain (“or truthfulness, only about sycophancy”) and now reads as the source does, “Our results say nothing about correctness”; the point it supports is unchanged. The §8.3 design rule is no longer stated as a law: an instrument the measured party can operate tends to rot; one it cannot alter is harder to game, though not immune. Zhang et al. (2026) is now read as a gain from training, not from moving a check outside the agent (§8.3, Figures 10 and 11). Laban et al. (2023) replaces Kelley and Riedl (2026), whose tasks have no ground truth, in Table 5 and H3. The 48% is now the share of operator turns the detector flagged, roughly a third adjusted; the 27× logging gap is about 19× adjusted and partly definitional. Table 9 separates measured counts from interpreted links, §13 offers its design rules as hypotheses, and the Disclosure says who read the cited works. A second pass the same day restored, in the author’s wording, positions that revision had softened for reasons other than fact, and labelled each for status (our position, conjecture, from one practice, measured) instead of hedging it; Table 9 now carries a Status column and §13 states its design rules as our position. Every factual correction above stands.
Works cited in this part (keys, including letter suffixes such as 2026b, follow the full paper’s reference list)
References
- Adler, S. (2025, October 2). Practical tips for reducing chatbot psychosis. Clear-Eyed AI. clear-eyed.ai
- Advani, L. (2026). From confident closing to silent failure: Characterizing false success in LLM agents. FAGEN Workshop at ICML 2026. arXiv:2606.09863. arxiv.org/abs/2606.09863
- Denisov-Blanch, Y., Kazdan, J., Chudnovsky, J., Schaeffer, R., Guan, S., Adeshina, S., & Koyejo, S. (2026). Consensus is not verification: Why crowd wisdom strategies fail for LLM truthfulness. arXiv:2603.06612. arxiv.org/abs/2603.06612
- Flynt, J. (2026). GroundEval: A deterministic replacement for LLM-as-judge in stateful agent evaluation. arXiv:2606.22737. arxiv.org/abs/2606.22737
- He, C., Chen, Z., Yang, Z., Qiao, S., Ju, M., Liu, J., Wen, D., & Liu, G. (2026). Minority Sentinel: When to overturn majority voting in multi-agent LLM debates. AgentSearch Workshop at SIGIR 2026. arXiv:2606.29270. arxiv.org/abs/2606.29270
- Ivanov, I., & Africa, D. D. (2026). LURE: Live-usage replay evaluations for reducing evaluation awareness. arXiv:2605.26438. arxiv.org/abs/2605.26438
- Kelley, S. W., & Riedl, C. (2026). Personalization increases affective alignment but has role-dependent effects on epistemic independence in LLMs. arXiv:2603.00024. arxiv.org/abs/2603.00024
- Kenton, Z., Janzer, L., Greig, R., Teh, T. H., Tyshchuk, K., Brown-Cohen, J., Edwards, H., Rajamanoharan, S., Siegel, N. Y., Jaques, N., et al. (2026). Debate training reduces reward hacking in RLAIF. arXiv:2608.17776. arxiv.org/abs/2608.17776
- Lamparth, M., Fein, D., Haupt, A., Hussing, M., & Kochenderfer, M. J. (2026). Reward bias substitution: Single-axis bias mitigations redirect optimization pressure. arXiv:2605.27996. arxiv.org/abs/2605.27996
- Liu, J. (2026). When may an agent stop? Evidence-carrying termination for tool-using LLMs. arXiv:2608.23623. arxiv.org/abs/2608.23623
- Mehta, A. (2026). When agents commit too soon: Diagnosing premature commitment in LLM agents. Snowflake AI Research. arXiv:2606.22936. arxiv.org/abs/2606.22936
- Pan, J., He, H., Bowman, S. R., & Feng, S. (2024). Spontaneous reward hacking in iterative self-refinement. arXiv:2407.04549. arxiv.org/abs/2407.04549
- Panickssery, A., Bowman, S. R., & Feng, S. (2024). LLM evaluators recognize and favor their own generations. arXiv:2404.13076. arxiv.org/abs/2404.13076
- Park, H., & Choi, B. (2026). When do agent loops mistake stagnation for progress? Self-evaluation bias and externally grounded verification in long-running autonomous LLM agent loops. arXiv:2607.25152. arxiv.org/abs/2607.25152
- Wan, Y., Fang, T., Li, Z., Huo, Y., Wang, W., Mi, H., Yu, D., & Lyu, M. R. (2026). Inference-time scaling of verification: Self-evolving deep research agents via test-time rubric-guided verification. Findings of ACL 2026. arXiv:2601.15808. arxiv.org/abs/2601.15808
- Wang, B., Zhang, C., Liu, D., Zhang, J., Chen, J., Li, M., Chen, M., Fang, R., Zhang, S., Wang, X., Jing, Y., Ma, Z., & Cui, Z. (2026). The verification horizon: No silver bullet for coding agent rewards. arXiv:2606.26300. arxiv.org/abs/2606.26300
- Wang, J., & Huang, J. (2026). Reward hacking as equilibrium under finite evaluation. arXiv:2603.28063. arxiv.org/abs/2603.28063
- Zhang, B., Zhu, J., Shi, Z., Liu, D., & Tang, R. (2026). AgentForesight: Online auditing for early failure prediction in multi-agent systems. arXiv:2605.08715. arxiv.org/abs/2605.08715
- Zhao, J., Bhattacharjee, H., Korevaar, H., Radharapu, B., & El-Arini, K. (2026). Jagged judges: Epistemic stability under perturbation, pressure, and persistence. arXiv:2608.12645. arxiv.org/abs/2608.12645
Prior art (cited at concept level; verified for author, title, year and venue, not read in full)
- Knight, J. C., & Leveson, N. G. (1986). An experimental evaluation of the assumption of independence in multiversion programming. IEEE Transactions on Software Engineering, SE-12(1), 96–109. doi.org/10.1109/TSE.1986.6312924
Software and documentation (read at the linked pages, September 2026; current as of then, not permanent)
- Anthropic. (2025, September 29). Building agents with the Claude Agent SDK. claude.com/blog/building-agents-with-the-claude-agent-sdk
- Anthropic. (2026a). How the agent loop works. Claude Agent SDK documentation. code.claude.com/docs/en/agent-sdk/agent-loop
- Anthropic. (2026b). Keep Claude working toward a goal. Claude Code documentation. code.claude.com/docs/en/goal
- CrewAI. (2026a). Agent output parser (source code). github.com/crewAIInc/crewAI, the agent output parser
- CrewAI. (2026b). Tasks. CrewAI documentation. docs.crewai.com/en/concepts/tasks
- Nous Research. (2026). Hermes agent (repository, configuration and issue tracker). github.com/NousResearch/hermes-agent
- OpenAI. (2024). Swarm (repository; experimental, superseded by the Agents SDK). github.com/openai/swarm
- OpenAI. (2026a). Running agents. OpenAI Agents SDK documentation. openai.github.io/openai-agents-python/running_agents/
- OpenAI. (2026b). Human in the loop. OpenAI Agents SDK documentation. openai.github.io/openai-agents-python/human_in_the_loop/
Press and public statements (§2.3; read at the linked pages, or at the named carrier where the original is paywalled)
- Fortune. (2026, September 12). Interview with the chief executive of OpenAI on safety and the timing of a public offering. fortune.com/2026/09/12/sam-altman-interview-ai-doomsday-safety-models-control-ipo-2027/