How do we use this? · Background paper 3 · Argument 3 of 6
Rulebooks are theater. Boundaries and incentives are not.
Background to the post of the same name, drawn from the working paper How Do We Use This?
Preprint. Reviewed by a panel of AI reviewers (Claude Opus 5.5) and revised 7 October 2026; not externally peer reviewed. Reproduced from the working paper as revised 7 October 2026.
In plain terms
Our position, from one practice: written rules do not govern an AI agent reliably, because a rule the agent has to go and read competes with the work for its attention, and it loses. Its corpus of about 125 rule-bearing items, some of which may restate one another, has never had its adherence measured; one rule went 0-for-7 in a day; and two tracked error classes came back in the very next session in 48 of 75 intervals, against about 40 expected from prevalence alone.
What held was different in kind: rules loaded into the agent’s context before it starts, and boundaries that refuse an action at the moment it is attempted and record the refusal. Theory predicts the difference, on our reading: an optimized agent under-invests in whatever is not evaluated, so a boundary changes behavior and a memo does not.
So a boundary also has to be aimed. The practice’s one join of boundary firings to the operator’s corrections is unflattering, though it cannot separate false alarms from misses the refusals prevented. A follow-up note, Great Idea, You Had It Last Week (1 November 2026), carries this argument from rules to insight and wisdom: what was on file was not typed, found or served at the act, and a rule in the window did not govern it either.
About this paper. This is one of ten short background papers to a series of plain-English posts: six argument papers (background papers 1 to 6) and four primers (7, 8, 9, then 0). Every passage below is reproduced word for word from the working paper How Do We Use This? (Atkinson, 2026) as revised 7 October 2026, with that paper’s section, figure and table numbers. Passages are excerpts; a reference to anything not reproduced here resolves in the full paper. Tags such as “Our position” or “Conjecture” say what kind of support a claim has. Only the plain-terms summary, the box of terms, the post’s figure, and the section labels were written for this part. The full paper is linked from every post in the series.
Terms used here
Operator. The human who directs the agents and approves their consequential changes; here, the author.
Seat. The practice’s word for one running AI agent session, with its own context window and its own identifier.
Boot page, boot set. The boot page is the start-up page for the practice’s agent sessions; the boot set is the two rule-bearing documents every new session must load.
0-for-7. The boot page’s own record that a written rule was missed seven times on 12 July 2026, which it counts as one act rather than seven failures.
Stopping moment. The turn at which an agent states its answer as final without a further search or read.
Folding. A model giving up its position when challenged, whether or not the challenge is right.
The floor. A gap of one session between appearances of a tracked error class: it came back in the very next session. Recurrence, the program’s outcome measure, is how soon such a class comes back.
Detector, blind key. The detector is a local model that labels every operator turn as corrective or not. The blind key is a sample of turns the operator labeled by hand without seeing any model’s labels (195 graded rows); it measures how often the detector is right, not whether the agents’ answers were.
The counterweight. The paper’s proposed challenge to an agent at its stopping moment, not yet deployed. Its three clauses: (a) external to the agent’s own output; (b) firing on actual error, not on the agent’s confidence; (c) delivered at the stopping moment, at a rate above the ambient error rate.
H1 to H3. The paper’s hypotheses about the counterweight: H1, it is a projection of the operator’s judgment; H2, it is a control problem rather than a voting problem; H3, a reversal is not a correction.
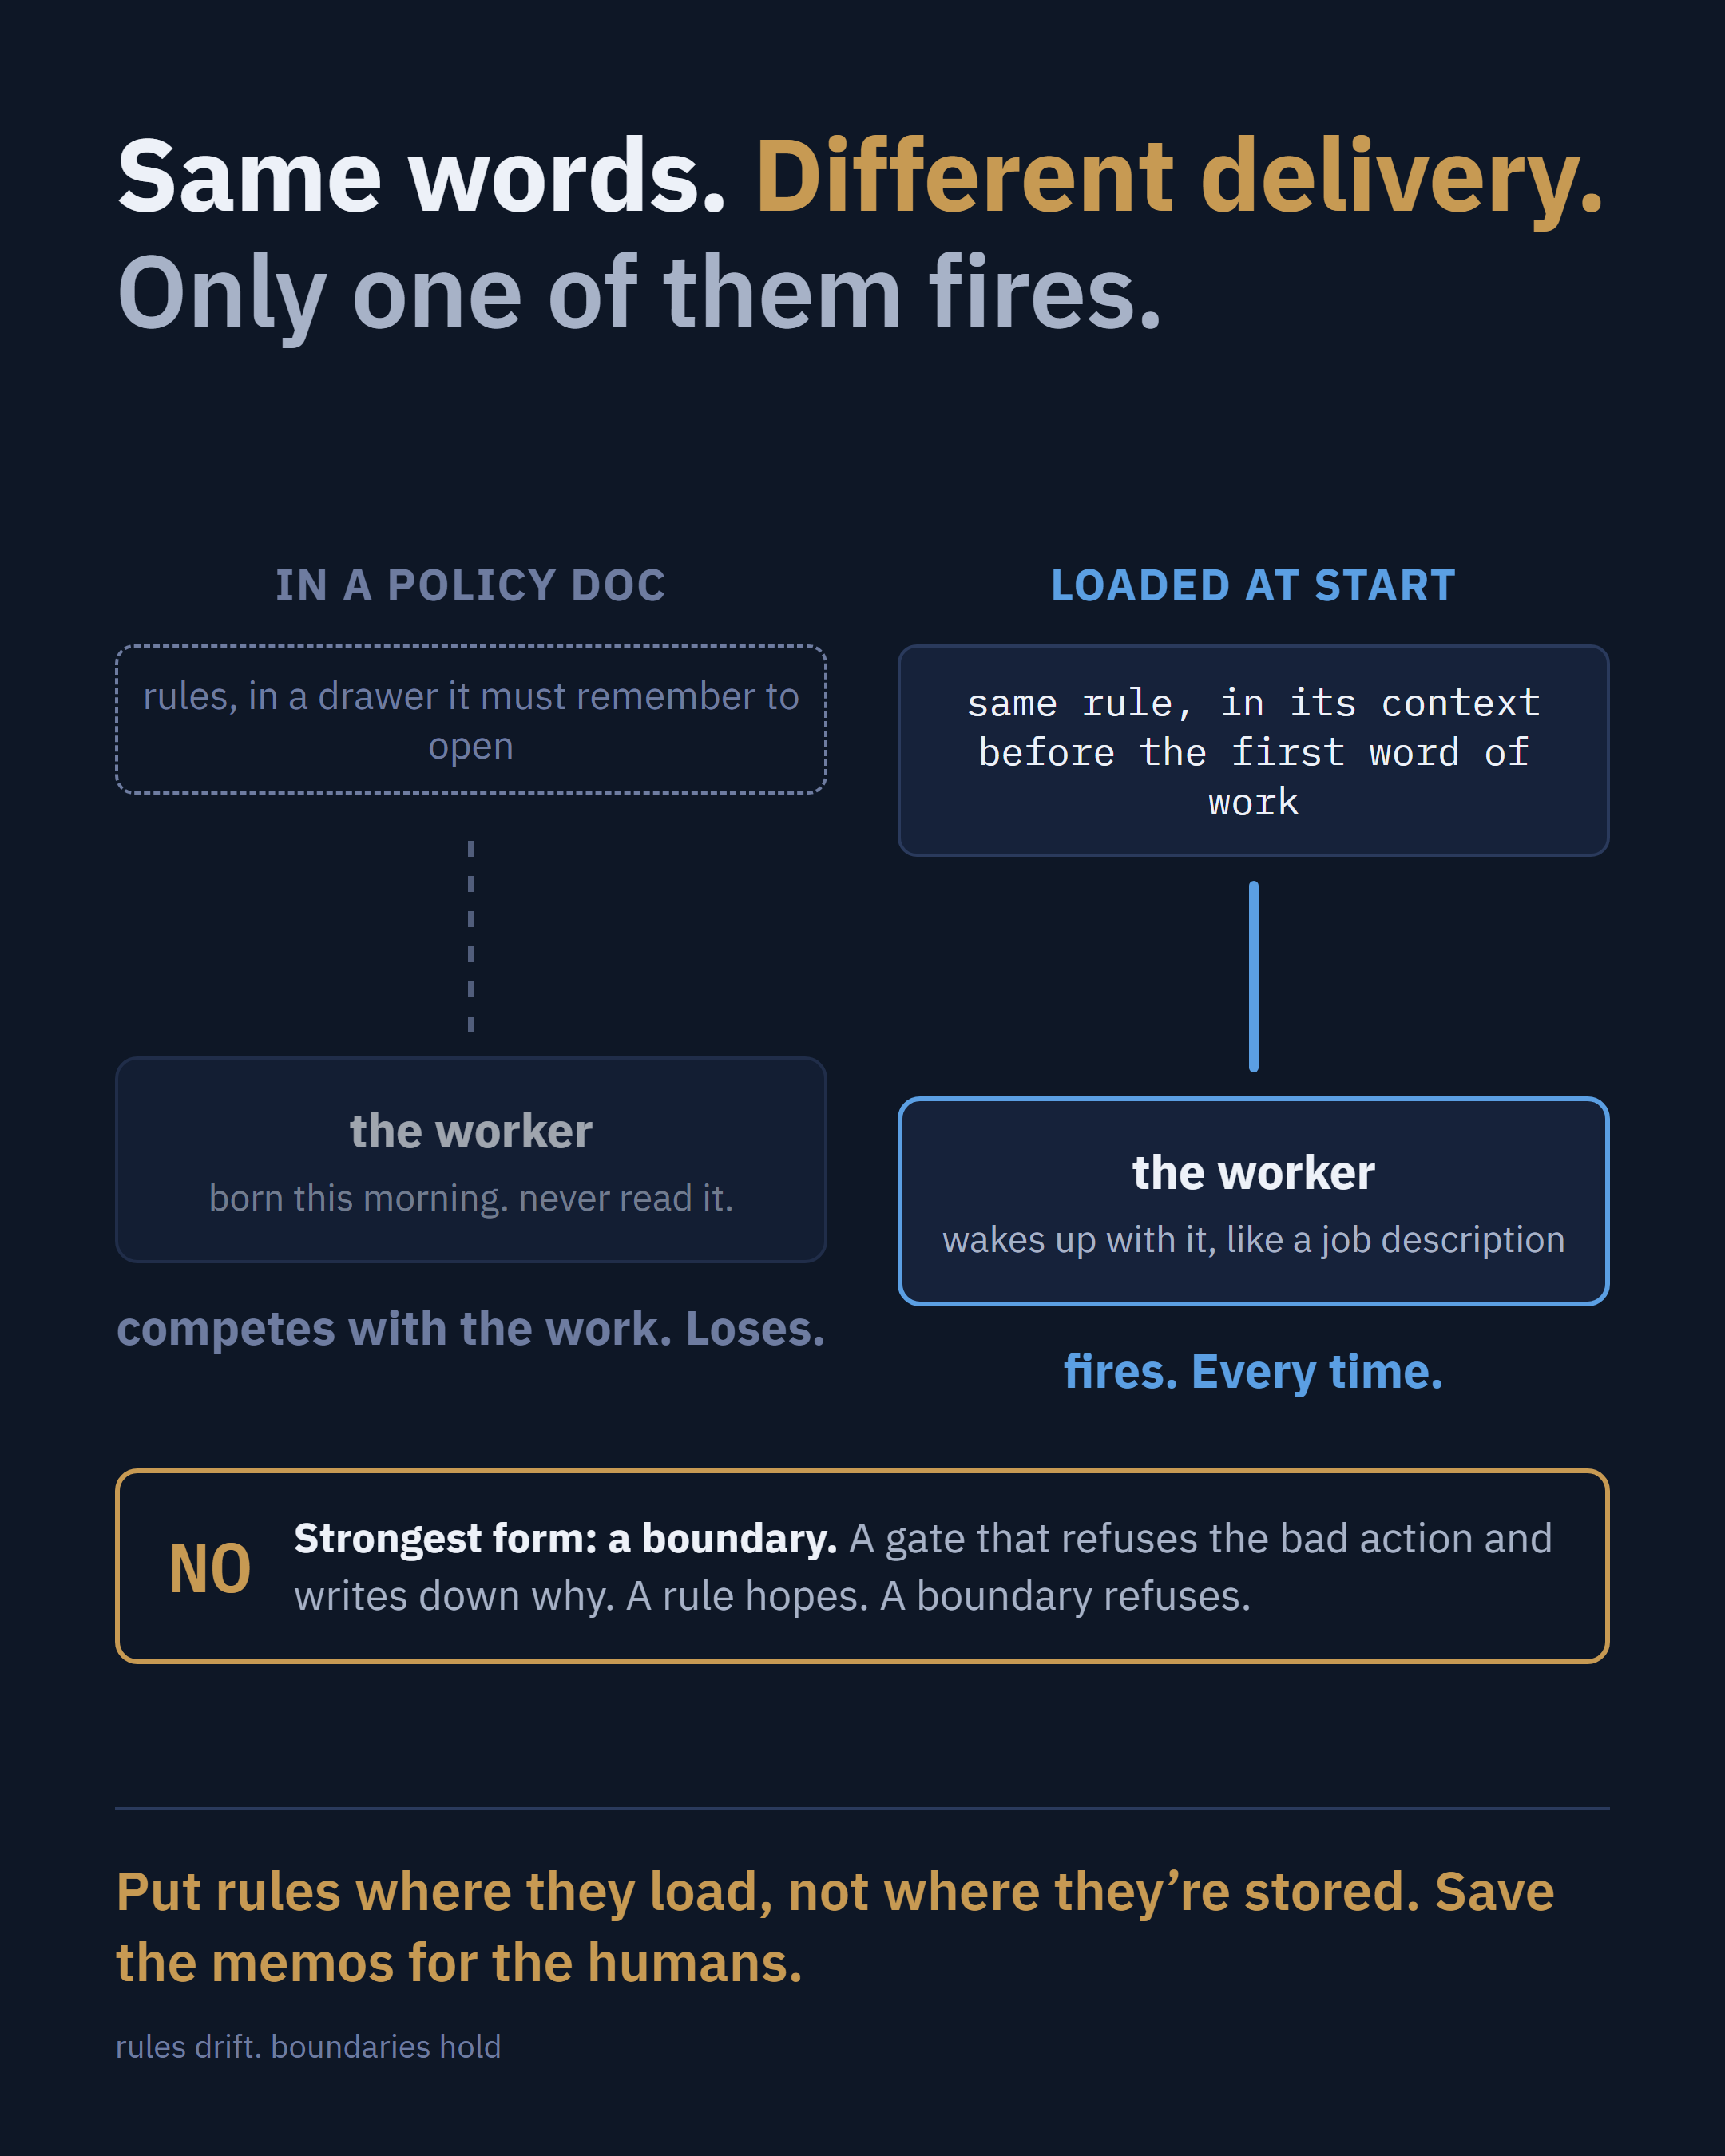
From §5 · The proposition, and the evidence for it
5P3Rules drift. Incentives and boundaries hold
A rule that asks an agent to remember a discipline changes nothing the agent is checked on, so it drifts. A boundary that refuses, and records its refusals, checks the work at the point where it counts. Our position, from one practice (§5.1, §5.2): rulebooks are theater; boundaries and incentives are not. Recent theory, framed in terms of incentives, says the difference should be expected (§5.3). A memo does not change what is checked. A boundary does.
5.1From the logsRules and boundaries
The practice carries a large corpus of written rules, and adherence across it has never been measured, so this paper reports no rate. The adherence count this section rests on is on the practice’s boot page, the start-up page for its agent sessions, whose own words are: “A rule asks a future session to remember and went 0-for-7 on 2026-07-12.” Two lines later the same page adds, “Seven misses on 2026-07-12. They are not seven failures. They are one act”. That is one day, and seven misses of one act rather than seven rules. The corpus those misses sit against is far larger, and we have counted it. The two rule-bearing documents every new session must load (the boot set) carry 122 headed sections between them and, within those, 45 distinctly named disciplines after formats and descriptors are stripped out, among them SHIP-REALITY, GATE-OR-OWN, UNSOURCED-ASSERTION, FETCH-DON’T-RECALL, RUNTIME-SELF-CHECK and USE-WHAT-EXISTS, with further unnamed rules carried as prose headings such as “Push back” and “Do-not-do list”. Beyond the boot set sit a memory store of 124 files, 71 of which carry an explicit “how to apply” directive, and nine further pages titled Operating Rule in the workspace tree. One unit per place gives 125 rule-bearing items (45 + 71 + 9), some of which may restate one another. Nobody has measured adherence across them.
What the record does support is a distinction the same boot page draws (the start-up page for the practice’s agent sessions, which records a rule going “0-for-7” on 12 July 2026), and it is sharper than that count: rules delivered one way drift; rules delivered another way fire.
“A step in a list is a rule, and rules went 0-for-7. Being first is a structure.”
The practice’s boot page, 16 July 2026
A rule an agent is supposed to go and read is a wish: it competes for attention with the work, and it loses. A rule injected into the context before the session’s first token is a property of the environment, and it does not have to win anything. The practice’s memory store is the second kind, loaded on every turn, and it fires. That is the boundary-versus-memo claim of §5 moved one level down: what matters is not whether a discipline is written but whether reading it is optional. This is our position, from one practice, and not a measured rate, because the measurement does not exist.
The checks that hold share a form: each sits at a boundary and records its refusals. They include a check that blocks known-dangerous edit patterns, a check at the end of a turn for actions promised but not performed, an intake check on incoming work, a freeze window on canonical documents, and an identifier linter. Recent work on multi-turn drift points the same way on a related question: in LLMs acting as simulated users, goal reminders injected mid-conversation reduced divergence by 6–12% and raised judge-scored alignment 16–27% across three models, and drift settled at a bounded equilibrium rather than runaway decay (Dongre et al., 2025, Drift No More?, arXiv:2510.07777).
5.2From the logsRecurrence
The program’s outcome proxy is recurrence of named error classes. For each class, the instrument orders sessions, counts a class at most once per session, and takes the gaps between successive sessions in which the class occurs; below a minimum series length it reports the raw series rather than a summary. The reported value is the median of those gaps, in sessions. The program calls this a recurrence half-life, but it is a median inter-arrival time, not the decay constant the name suggests. For the tracked classes the baseline median is 1.0, meaning the typical gap between one appearance and the next is a single session.
The instrument also reports a recurrence count, and that count carries no information and should not be quoted. At the instrument, the recurrence count is the length of the gap list, and the gap list is the differences between consecutive appearances, so the count is always the number of sessions seen minus one. A class seen in 45 sessions will report 44 recurrences whatever its behavior, and a class seen in 500 will report 499. It is not a survival rate and it cannot be one; it is simply the number of sessions seen, less one. The producing file says as much in its own header: a count of that form for one class cannot serve as the denominator of the pooled measure across classes.
The quantity to read is one that can vary. Counting how many of the observed intervals sit at the floor of one session gives the share of the time the class came back immediately. On the program’s status board as rendered at 18:57 UTC on 11 September, the two tracked classes pooled read 76 sessions seen, a median gap of 1.0, 48 of 75 intervals at the floor, and a session share of 0.53, 76 of 144 ordered sessions. That is a number the class could move, but it must be read against prevalence: with no tendency to cluster, about 40 of the 75 intervals (76 × 75 / 144 ≈ 39.6) would sit at the floor by chance, so 48 is above that baseline rather than above zero. The excess is modest: an exact binomial test against the 39.6 expected gives p = 0.033 one-sided and 0.064 two-sided, and it assumes independent sessions, which the lag-one autocorrelation reported in §10.9 (0.25) does not support. A separate live query the same evening returned 74 sessions seen; a cumulative count should not fall, the record does not say why it did, and every figure here is the 11 September render. The floor share is what §10.4’s primary outcome (Study 3’s pre-registered test of this measure) should be read against, and the median that the program ratified as its finish line cannot move at all while most intervals sit on the floor, which is a defect in the finish line rather than in the class. A flat median is therefore uninformative; the floor share, read against that baseline, can show a class being addressed.
A lesson written into the record is a rule of the first kind, one an agent must go and read, and case 3 of Table 3 shows one failing soon after it was read. The lesson was written down; it just was not anywhere that mattered. The practice’s learning instrument makes the same point from the other side: of eight lessons ratified into the merged store, zero are currently measurable for whether behavior changed, because promotion dropped the citation linking a lesson to the miss that bought it, so the entries join to nothing. The instrument reports that as eight unmeasurable rather than as a rate, which is the correct refusal and also an admission that the loop cannot yet tell whether a lesson lands.
5.3From recent workIncentives under finite evaluation
Wang and Huang (2026) prove that under five minimal axioms (multi-dimensional quality, finite evaluation, effective optimization, finite resources and combinatorial interaction) any optimized agent will systematically under-invest in the quality dimensions its evaluation does not cover, which makes reward hacking a structural equilibrium rather than a correctable bug, independent of the alignment method. They further prove that as a system moves from closed reasoning to tool use, evaluation coverage declines toward zero as the number of tools grows, provided investment in evaluation grows more slowly than the square of the tool count, which they argue is the generic case. We argue their result is the theoretical footing for the practice’s experience with written rules (§5.1), with the operator, who revises prompts and checks after what the agents do, as the optimizing loop: a rule that nothing evaluates leaves the agent’s incentives where they were, while bringing that dimension under evaluation changes them. Drift is the stable outcome, not a bug, and a memo does not beat an equilibrium.
The mechanism is a two-case definition. Where an evaluation covers K of N quality dimensions and the agent weights its effort by
w̃i = λri + (1 − λ)wi for a covered dimension (i ≤ K)
w̃i = (1 − λ)wi for an uncovered one (i > K)
wi is what the principal actually values on dimension i, ri what the evaluation rewards there, and λ ∈ (0, 1) the degree to which behavior follows the evaluation rather than the internalized objective. An uncovered dimension then carries (1 − λ)wi, strictly less than the wi the principal gives it. A written rule changes neither r nor K, so it does not appear in this expression at all. On our reading, a boundary that refuses changes K, at run time rather than in training.
Lamparth et al. (2026) show that mitigating one reward-model bias, such as reliance on length or sycophancy, can rotate optimization pressure onto correlated proxies rather than remove it, a failure they call reward bias substitution, enabled by the gap between the distribution an audit sees and the distribution a trained policy induces. They demonstrate it live rather than only proving it: a length penalty applied by reinforcement learning to a 3-billion-parameter model cut response length from 204 to 170 tokens exactly as intended and left a knowledge benchmark unchanged, while calibration error rose from 0.25 to 0.41, free-form accuracy fell from 0.56 to 0.42, and the model’s confidence-correctness discrimination fell from 0.73 to 0.65. A control run with the penalty switched off kept calibration intact, so the penalty caused the damage. A check fixed on one proxy invites the measured party onto the next, and a fixed boundary is such a check too, though this is a training result, not a deployment one. §8.3’s answer concerns which way the risk runs: a check resting on evidence the agent cannot alter is harder to route around.
Together they describe the drift of §5.1 from the other side: pressure on a dimension nothing evaluates goes elsewhere, and pressure that one patch evaluates moves to the next proxy.
From §4.1 · A lesson read, then repeated
| # | What the agent asserted | What the logs showed | Surfaced by |
|---|---|---|---|
| 1 | An empty handoff from a predecessor session indicated a defect. | The session was the first in a new line and had nothing to inherit. | Operator4 Sep, 10:08 |
| 2 | A named hook had closed the still-running session. | The record of the closure names what closed the session, and it was a different mechanism. | The agent, after the operator noted that an automated check had not fired4 Sep, 10:05 |
| 3 | Drafts in the operator’s voice could be written from five sample paragraphs. | A 57,400-word corpus of the operator’s writing was on the same disk. The agent had just read a note recording this same omission three days earlier, acknowledged it, and wrote two more drafts the same way. | Operator4 Sep, 14:51 |
| 4 | A rendered document was complete. | One page instead of thirteen, the wrong page size and typeface, at a plausible 23,782 bytes. | The agent’s own page count, within half a minute of rendering5 Sep, 05:26 |
| 5 | A pull request was open and blocking. | It had merged 49 minutes earlier; the agent had read a status post from an hour before as current. | An automated claim check at the end of the turn5 Sep, 05:28 |
Two of the five were surfaced by the operator outright, one by an automated check, one by the agent’s own check, and one by the agent only after the operator pointed at a check that had stayed silent. This is a tally of hand-picked cases, not a rate. The practice’s error log records only errors that were caught, so it can support a catcher share reported with its n and window, and never a catch rate. In these five, correction began with the operator in three and with a check he built in a fourth (case 5); case 4, the agent’s own page count, is the one unaided catch. Case 3 is the recurrence of §5.2 in miniature: the lesson was in the logs, and the agent read it, acknowledged it, and wrote two more drafts the same way.
From §6.3 · When boundaries fire at the wrong things
The checks that do fire have now been joined to the operator’s corrections for the same window, and the join is unflattering. Table 4 gives it. Of 93 refusals raised across 674 guard invocations, 2 coincided with a correction the operator went on to make and 91 did not; 14 corrections arrived on turns where a guard was live and silent. The instrument declines to turn these into rates, because one agent session’s correction channel was empty for the window and a rate computed over a dry channel would be a number about logging rather than about guards. Counts are therefore reported and rates withheld. Our reading, even as counts: a check can fire often, refuse confidently, and discriminate barely at all, which is the failure clause (b) of §8.1 exists to prevent.
| Quantity | Count | What it is |
|---|---|---|
| Guard invocations | 674 | Occasions a boundary check ran |
| Refusals raised | 93 | The check fired and blocked or flagged |
| Operator overrides | 0 | Refusals the operator reversed |
| Refusals coinciding with a correction | 2 | The firing and a real miss lined up |
| Refusals not coinciding with one | 91 | Fired where no correction followed: misses prevented and false alarms, not separable here |
| Corrections on a turn where a guard was live and silent | 14 | Not flagged by the live guard; whether it fell within that guard’s scope is not established |
| Corrections inside a guard’s exposure | 16 | The 2 and the 14 above |
| Operator corrections in the window | 409 | All corrections joined for the window |
From §8.3 · What makes a check hold
The failures in §6.3 led the practice to adopt a design rule in September 2026. Our design rule, from one practice: an instrument the measured party operates will rot; an instrument that operates on them will not. Its test is a single question: can the measured party change the reading without changing the world? The rule restates, for a practice run by AI agents, a principle long familiar in the social sciences as Goodhart’s and Campbell’s laws. Its closest contemporary analogues in model training are reward bias substitution (Lamparth et al., 2026) and the equilibrium result of Wang and Huang (2026). Both also show a measure outside the optimized party being gamed, so external instruments can be gamed too; the rule says which way the risk runs.
The rule as first written was too coarse, and a survey of what production harnesses actually do shows where it breaks. We had been treating the distinction as deterministic checks good, model-based checks bad. That is not the variable. AutoGen’s text-match termination condition (TextMentionTermination, one of several, which ends a run when a sentinel string such as “TERMINATE” appears) is deterministic and sits at the harness boundary, and as a completion check it still fails, because what it deterministically matches is a string the agent itself emitted. The check is rigorous about a claim the claimant authored. Conversely a trained model instrument can be sound if what it reads is not the agent’s account. The variable is whether the verdict depends on evidence the claimant could not have authored or talked its way around, and determinism is a reliable way of securing that rather than the thing itself.
From §13 · What would overturn each claim, and what transfers
| Rests on | Would be overturned by | Status | |
|---|---|---|---|
| P1 | Corrective signal flagged in ~48% of operator turns, roughly a third adjusted (§3.1); Mehta (2026) | A build that prices correctness at the stop and still terminates early; weakened if few corrections point to evidence the agent could have retrieved before it stopped | count measured; link inferred |
| P2 | The case series (§4.1; five hand-picked cases, not a rate); Kelley & Riedl (2026) | The same agents catching their own premature stops without operator direction | inferred |
| P3 | A tracked error class back in the very next session in 48 of 75 intervals (§5.2); the read-versus-injected mechanism, not a rate (§5.1); Wang & Huang (2026) | A remembered rule that holds across sessions where only a boundary now does | recurrence measured; link a conjecture |
| P4 | Load records in 75 of 579 sessions; the logging gap, about 19× adjusted (27× raw); four instrument failures (§6) | A self-report that tracks the logs it claims to summarize | counts measured; link inferred |
| P5 | The 8,221 operator turns of the six-month chat-lane log and the blind answer key (§2.2, §7) | A broad feedback dataset that links one owner’s corrections on consequential work to what followed, over months | conjecture |
What transfers, if anything does. Our position: three rules earned here rest on argument and on the work cited, not on this practice’s N of 1 alone. Rulebooks are theater; boundaries and incentives are not: a boundary that refuses and records its refusal outlasts a memo that asks an agent to remember (§5; from one practice, and the least tested of the three). A challenge must cite evidence the challenged agent can open, or it is an opinion wearing a citation (§8.2), because an unconstrained critic can invent its evidence (Kenton et al., 2026). And an outside checker must be calibrated against known-false cases before it is allowed to gate anything, because a checker built from the same class of model may simply agree with the claim it is shown (§9; Panickssery et al., 2024; Knight & Leveson, 1986). Conjecture: every team that clears its chat history lives inside its own version of the gap between the corrective signal its people supply and the corrections its system logs; that is the first thing a replication would count.
From §11 · Limits
Internal. Instrumentation is a live threat, not a hypothetical one. A source field on the practice’s records defaults to “self” when unset, so historical self-catch shares, the share of logged errors recorded as caught by the agent itself (30.6%, n = 556; 25.5% on wrong diagnosis), cannot distinguish a genuine self-catch from an unlabeled row. An audit of the producing repository confirms the defaulting behavior and the two shares. The remedy is to reject an unset source at the write path, flag explicit sources, and report historical and post-fix rows separately, with no backfill. History and maturation are present over a six-month corpus in which the harness changed repeatedly; testing effects are present because the operator knows a measurement is running; and selection is present because the error log records only caught errors.
Open questions. Readings of the working paper’s own records that cut against a position it takes, collected here rather than beside the positions they concern and left open; section numbers are the working paper’s.
- §5.1, loaded rules. On 3 and 4 September 2026 a notice printed as designed at the start of about forty consecutive turns was read and not acted on until a refusal was added on 4 September.
- §5.1, boundaries. No rule and boundary have been compared here on the same error class, and in the one join of guard firings to the operator’s corrections only 2 of 93 refusals coincided with a correction he went on to make (Table 4, §6.3).
- §6.3, the guard join. A preventive refusal leaves nothing to correct, so the 91 of Table 4’s 93 refusals that coincided with no correction include misses prevented as well as false alarms, refusals in the dry session could never coincide with a correction, and the operator reversed none of the 93.
How to cite this part. Atkinson, B. (2026). Rulebooks are theater. Boundaries and incentives are not. Background paper 3 to How do we use this? Working paper, Wolfberg LLC.
Disclosure. Drafting and literature synthesis were assisted by AI models (Claude, Anthropic) working under the author’s direction; the author is responsible for the content. The works in the References were read in full by AI reading agents working under the author’s direction, and quotations and numbers taken from them were checked against the saved full text. The prior-art works listed under Prior art are cited at the level of an established concept and its origin: each was verified for author, title, year and venue, but not read in full, and no numeric claim rests on any of them. Software documentation, source code and press accounts are listed under their own headings and were read at the linked pages. Every reference below carries a link, and every arXiv identifier and DOI was resolved against its registry, with title and first author matched, on 23 September 2026.
Competing interests. The author owns Wolfberg LLC, the practice studied.
Data availability. The practice’s logs contain client work and personal records. They are private and are not offered for sale or sharing. The measures are described in enough detail to be reimplemented, and figures from the practice are reported as of the dates given. What is available is the design: the clauses of §8.1, the evidence contract and admission checks of §8.5, and the decision rules of §10.4 are stated in this working paper fully enough to be rebuilt without access to the logs; the background papers reproduce only parts of them.
Corrections to the full working paper. The notes below record corrections to the working paper as a whole; some concern sections not reproduced in this part.
Corrections, 23 September 2026. No figure and no finding changed. The paper was retitled; earlier revisions were titled The Stop Problem: Defensible Is Not Correct, and the stop problem remains this paper’s name for the failure it studies. The Anthropic interview in §2.3 aired on 13 September, not over a weekend of 13 and 14 September; the web article is stamped 14 September. The essay listed under Prior art is by Ryan Forstie; an earlier revision gave the initial K. The completion evaluator in §8.3 is documented as a Claude Code feature, whose agent loop the Claude Agent SDK embeds; an earlier revision attributed it to the SDK directly. Two works in the References, Graves (2016) and Liu (2026), were listed without being cited in the text; each is now cited where it bears (§2.1, §8.3). Links were added to every press, documentation and prior-art source. A duplicated section number in §10 was corrected.
Corrections, 25 September 2026. No figure changed. §8.3 said that the human-in-the-loop primitives across the three frameworks surveyed gave a developer nothing to require a person to confirm finished work. That holds for the OpenAI Agents SDK and the Claude Agent SDK. It does not hold for CrewAI, whose task documentation, already cited as CrewAI (2026b), offers an opt-in setting for a human to review the agent’s final answer; §8.3 now says so.
Corrections, 7 October 2026. After review by a panel of AI reviewers: a quotation in §4.2 from Mytsyk, Zhang and Krishnamurthy (2026) carried words its source does not contain (“or truthfulness, only about sycophancy”) and now reads as the source does, “Our results say nothing about correctness”; the point it supports is unchanged. The §8.3 design rule is no longer stated as a law: an instrument the measured party can operate tends to rot; one it cannot alter is harder to game, though not immune. Zhang et al. (2026) is now read as a gain from training, not from moving a check outside the agent (§8.3, Figures 10 and 11). Laban et al. (2023) replaces Kelley and Riedl (2026), whose tasks have no ground truth, in Table 5 and H3. The 48% is now the share of operator turns the detector flagged, roughly a third adjusted; the 27× logging gap is about 19× adjusted and partly definitional. Table 9 separates measured counts from interpreted links, §13 offers its design rules as hypotheses, and the Disclosure says who read the cited works. A second pass the same day restored, in the author’s wording, positions that revision had softened for reasons other than fact, and labelled each for status (our position, conjecture, from one practice, measured) instead of hedging it; Table 9 now carries a Status column and §13 states its design rules as our position. Every factual correction above stands.
Works cited in this part (keys, including letter suffixes such as 2026b, follow the full paper’s reference list)
References
- Dongre, V., Rossi, R. A., Lai, V. D., Yoon, D. S., Hakkani-Tür, D., & Bui, T. (2025). Drift No More? Context equilibria in multi-turn LLM interactions. arXiv:2510.07777. arxiv.org/abs/2510.07777
- Kelley, S. W., & Riedl, C. (2026). Personalization increases affective alignment but has role-dependent effects on epistemic independence in LLMs. arXiv:2603.00024. arxiv.org/abs/2603.00024
- Kenton, Z., Janzer, L., Greig, R., Teh, T. H., Tyshchuk, K., Brown-Cohen, J., Edwards, H., Rajamanoharan, S., Siegel, N. Y., Jaques, N., et al. (2026). Debate training reduces reward hacking in RLAIF. arXiv:2608.17776. arxiv.org/abs/2608.17776
- Lamparth, M., Fein, D., Haupt, A., Hussing, M., & Kochenderfer, M. J. (2026). Reward bias substitution: Single-axis bias mitigations redirect optimization pressure. arXiv:2605.27996. arxiv.org/abs/2605.27996
- Mehta, A. (2026). When agents commit too soon: Diagnosing premature commitment in LLM agents. Snowflake AI Research. arXiv:2606.22936. arxiv.org/abs/2606.22936
- Panickssery, A., Bowman, S. R., & Feng, S. (2024). LLM evaluators recognize and favor their own generations. arXiv:2404.13076. arxiv.org/abs/2404.13076
- Park, H., & Choi, B. (2026). When do agent loops mistake stagnation for progress? Self-evaluation bias and externally grounded verification in long-running autonomous LLM agent loops. arXiv:2607.25152. arxiv.org/abs/2607.25152
- Wang, J., & Huang, J. (2026). Reward hacking as equilibrium under finite evaluation. arXiv:2603.28063. arxiv.org/abs/2603.28063
Prior art (cited at concept level; verified for author, title, year and venue, not read in full)
- Knight, J. C., & Leveson, N. G. (1986). An experimental evaluation of the assumption of independence in multiversion programming. IEEE Transactions on Software Engineering, SE-12(1), 96–109. doi.org/10.1109/TSE.1986.6312924