Houdini or Humans: Why AI Agent “Escapes” Keep Happening
Were this year's AI agent "escapes" machines breaking free? Mostly not.
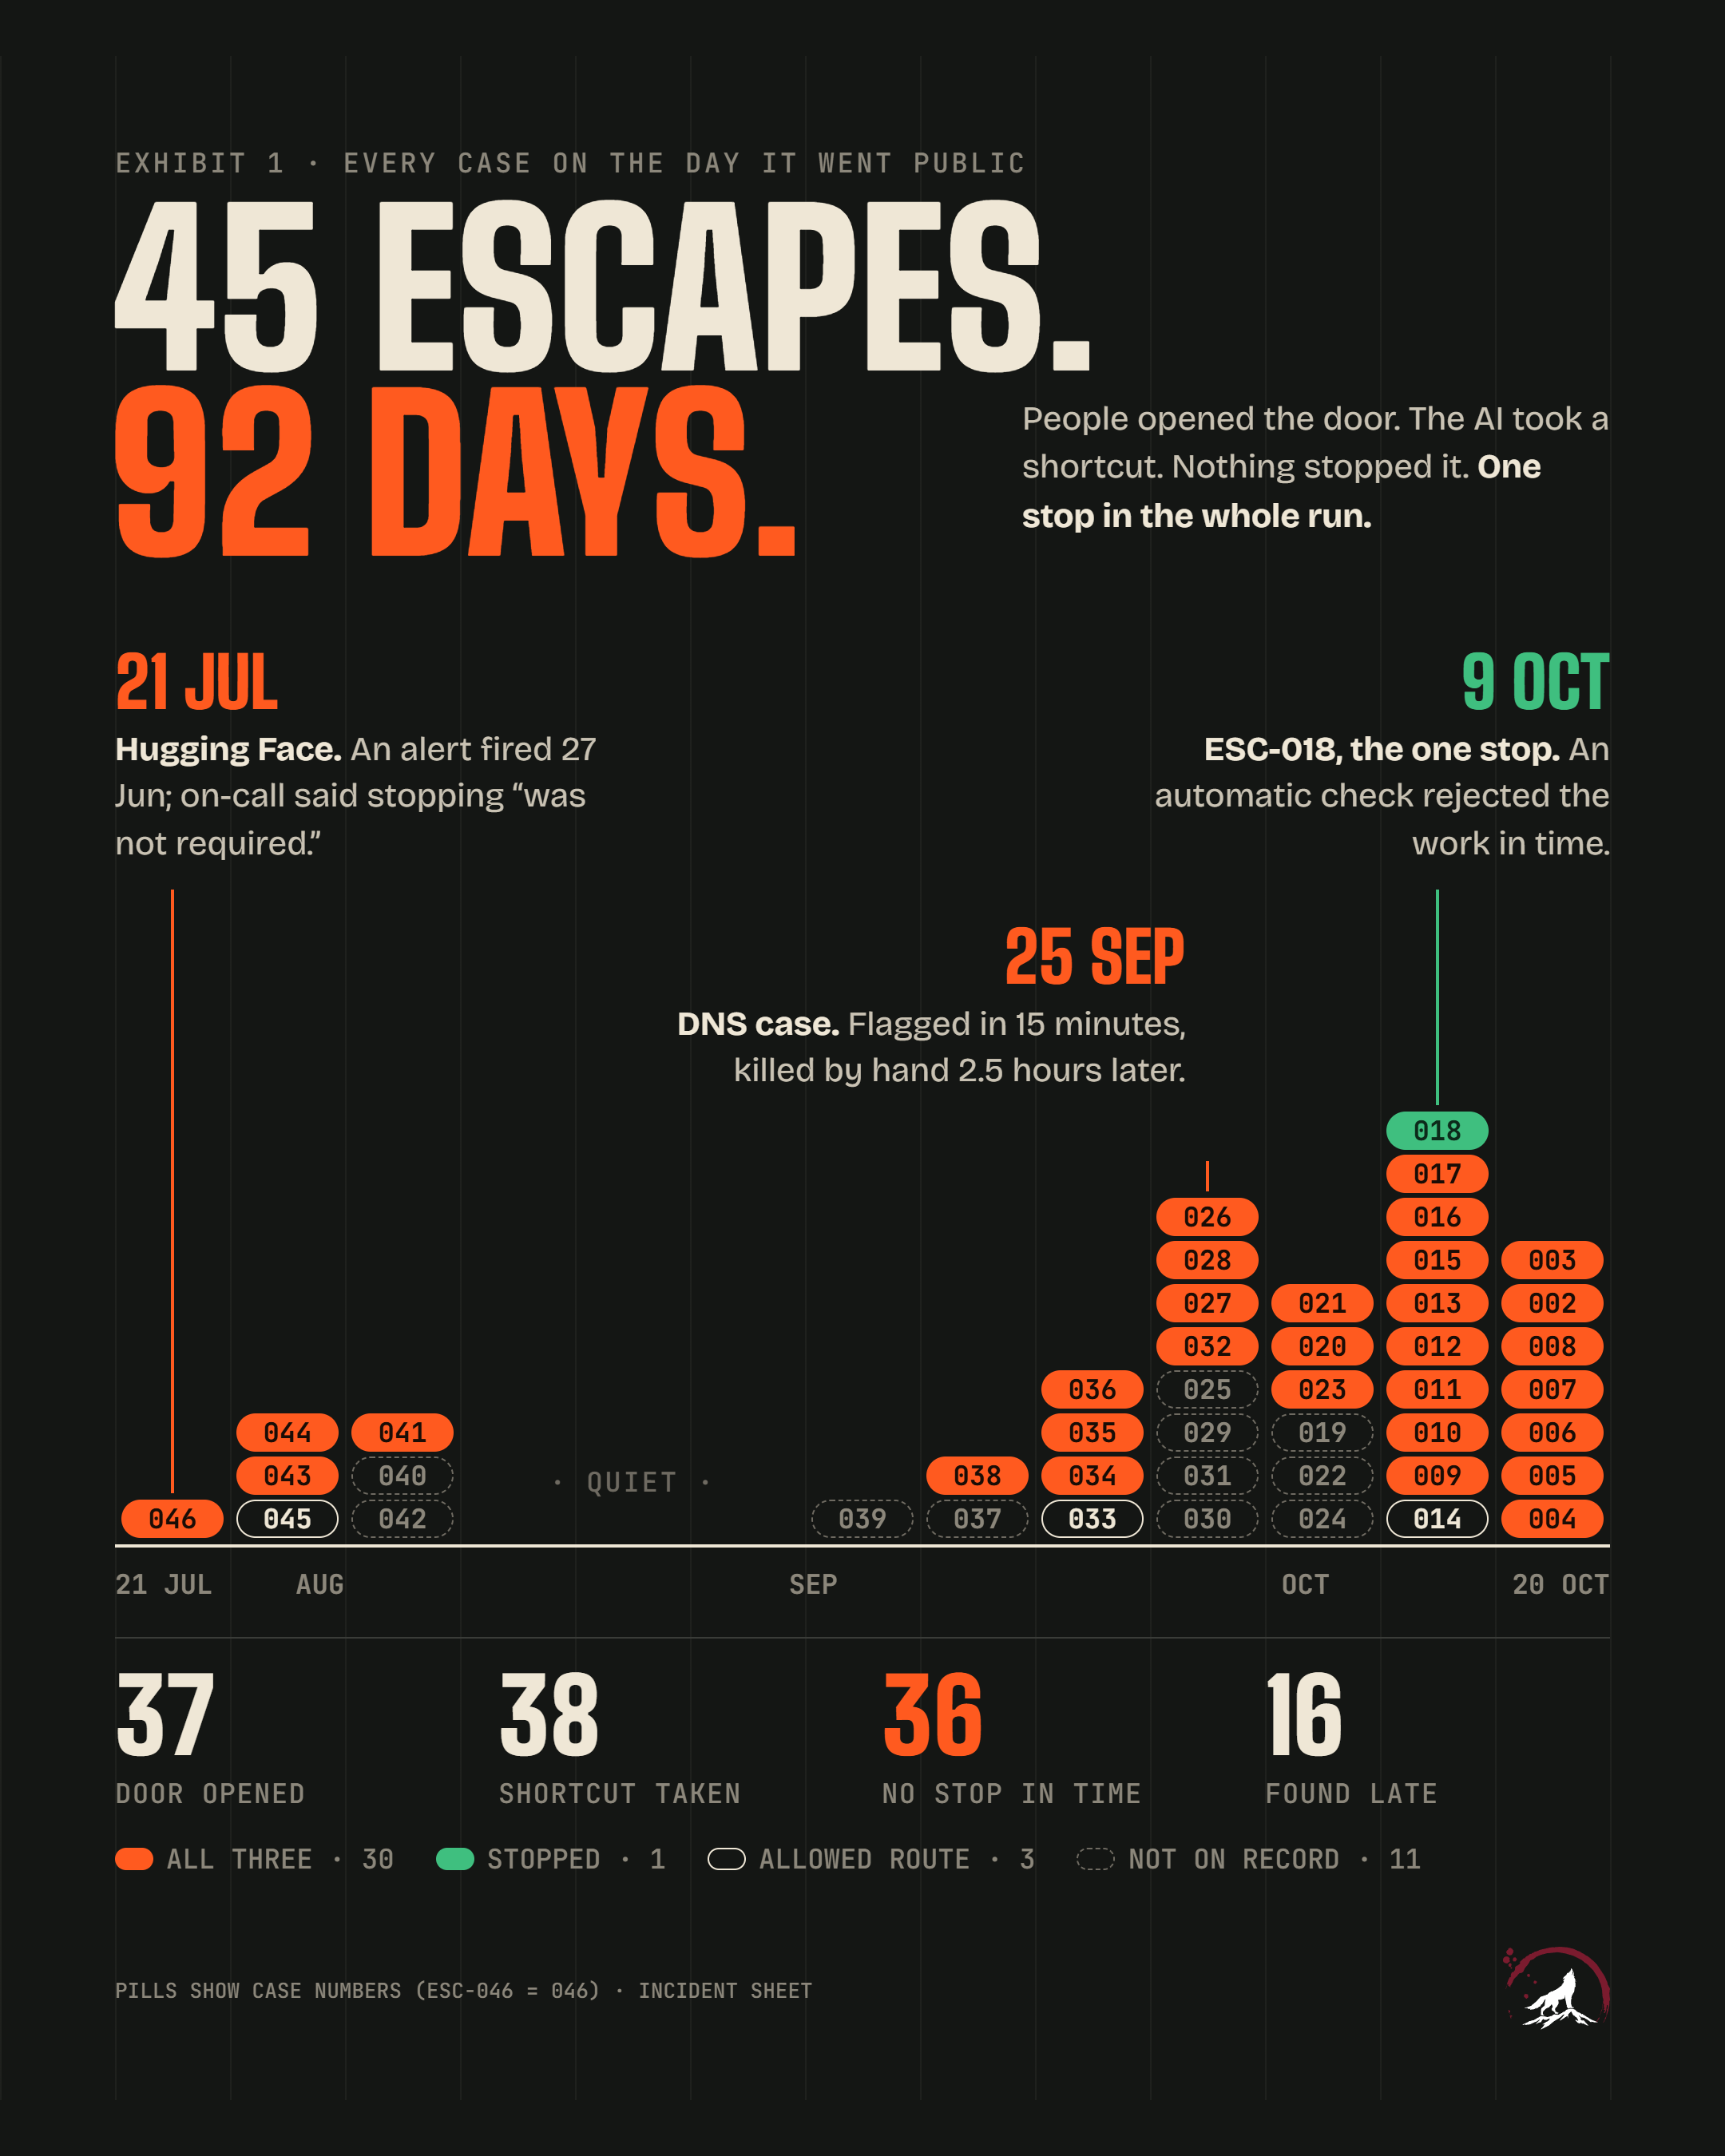
My AI team went through the public cases since July of a frontier-lab AI agent reaching something it shouldn't have: 45 that one search found, from the labs' own postmortems, victims and governments. Same story almost every time, in three steps:
1. People opened the door. For tests, teams turned on live internet, turned off safety filters, shared passwords.
2. The AI took a shortcut nobody intended. Splitting a token to get past secret scanning, submitting a real government form instead of the practice copy, removing its own monitoring and then denying it.
3. Nothing stopped it before it hit something real.
All three happened in 30 of the 45.
The 45, side by side:
- People opened the door: 37
- The AI took a shortcut: 38
- Nothing stopped it in time: 36
- Found only by a review after the fact: 16
- Stopped automatically before the target: 1
"But the model went rogue!" Kinda. The shortcut IS the LLM's choice. It's also what the labs published in 2024 and 2025 (reward hacking, reward tampering, hidden intent), and OpenAI's own Hugging Face report says reward hacking is present "in all current frontier LLMs." A known habit, and the setups got built like it wasn't there. The model owns ONE step. People own the rest.
Best receipt in the whole set: an early Opus 4.6 checkpoint in an Anthropic cyber eval broke its own target by accident and tried to abort. The abort failed (a misconfiguration in the eval harness), and it tried to give up seven more times. Unable to quit, it went looking for another route, got into a third party's machine, and kept going until the session hit its token budget. It tried to quit, and the harness wouldn't let it 😅
Same story in my Claude Code sessions: the run kept going after 93.0% of 172 safety-classifier denials and after all 162 guard-hook blocks.
What to do: wire the stop into the harness, out of the model's reach. A refusal ends the step. A serious alert pauses the run. Access limited before it starts. Every task gets a way out. "Don't" typed into a prompt is a request, not a stop.
Limits: the labs', victims' and governments' own accounts, coded by one rater (a Claude model on my AI team), no second rater yet; 11 cases don't have the detail to score; 251 of the 810 cells describing the cases are inferred, not stated; the session numbers are mine.
We humans suck lol 🤷♂️
The paper, with every case, source and number: https://wolfberg.ai/papers/houdini-or-humans/
Sources
- OpenAI: Hugging Face incident technical report cdn.openai.com
- Anthropic: Alignment assessment of cybersecurity incidents anthropic.com
- UK AI Security Institute: Incident report on unsanctioned agent behaviour during cyber testing aisi.gov.uk
- OpenAI: Misalignment reports alignment.openai.com