Great Idea, You Had It Last Week: Insight Doesn’t Survive
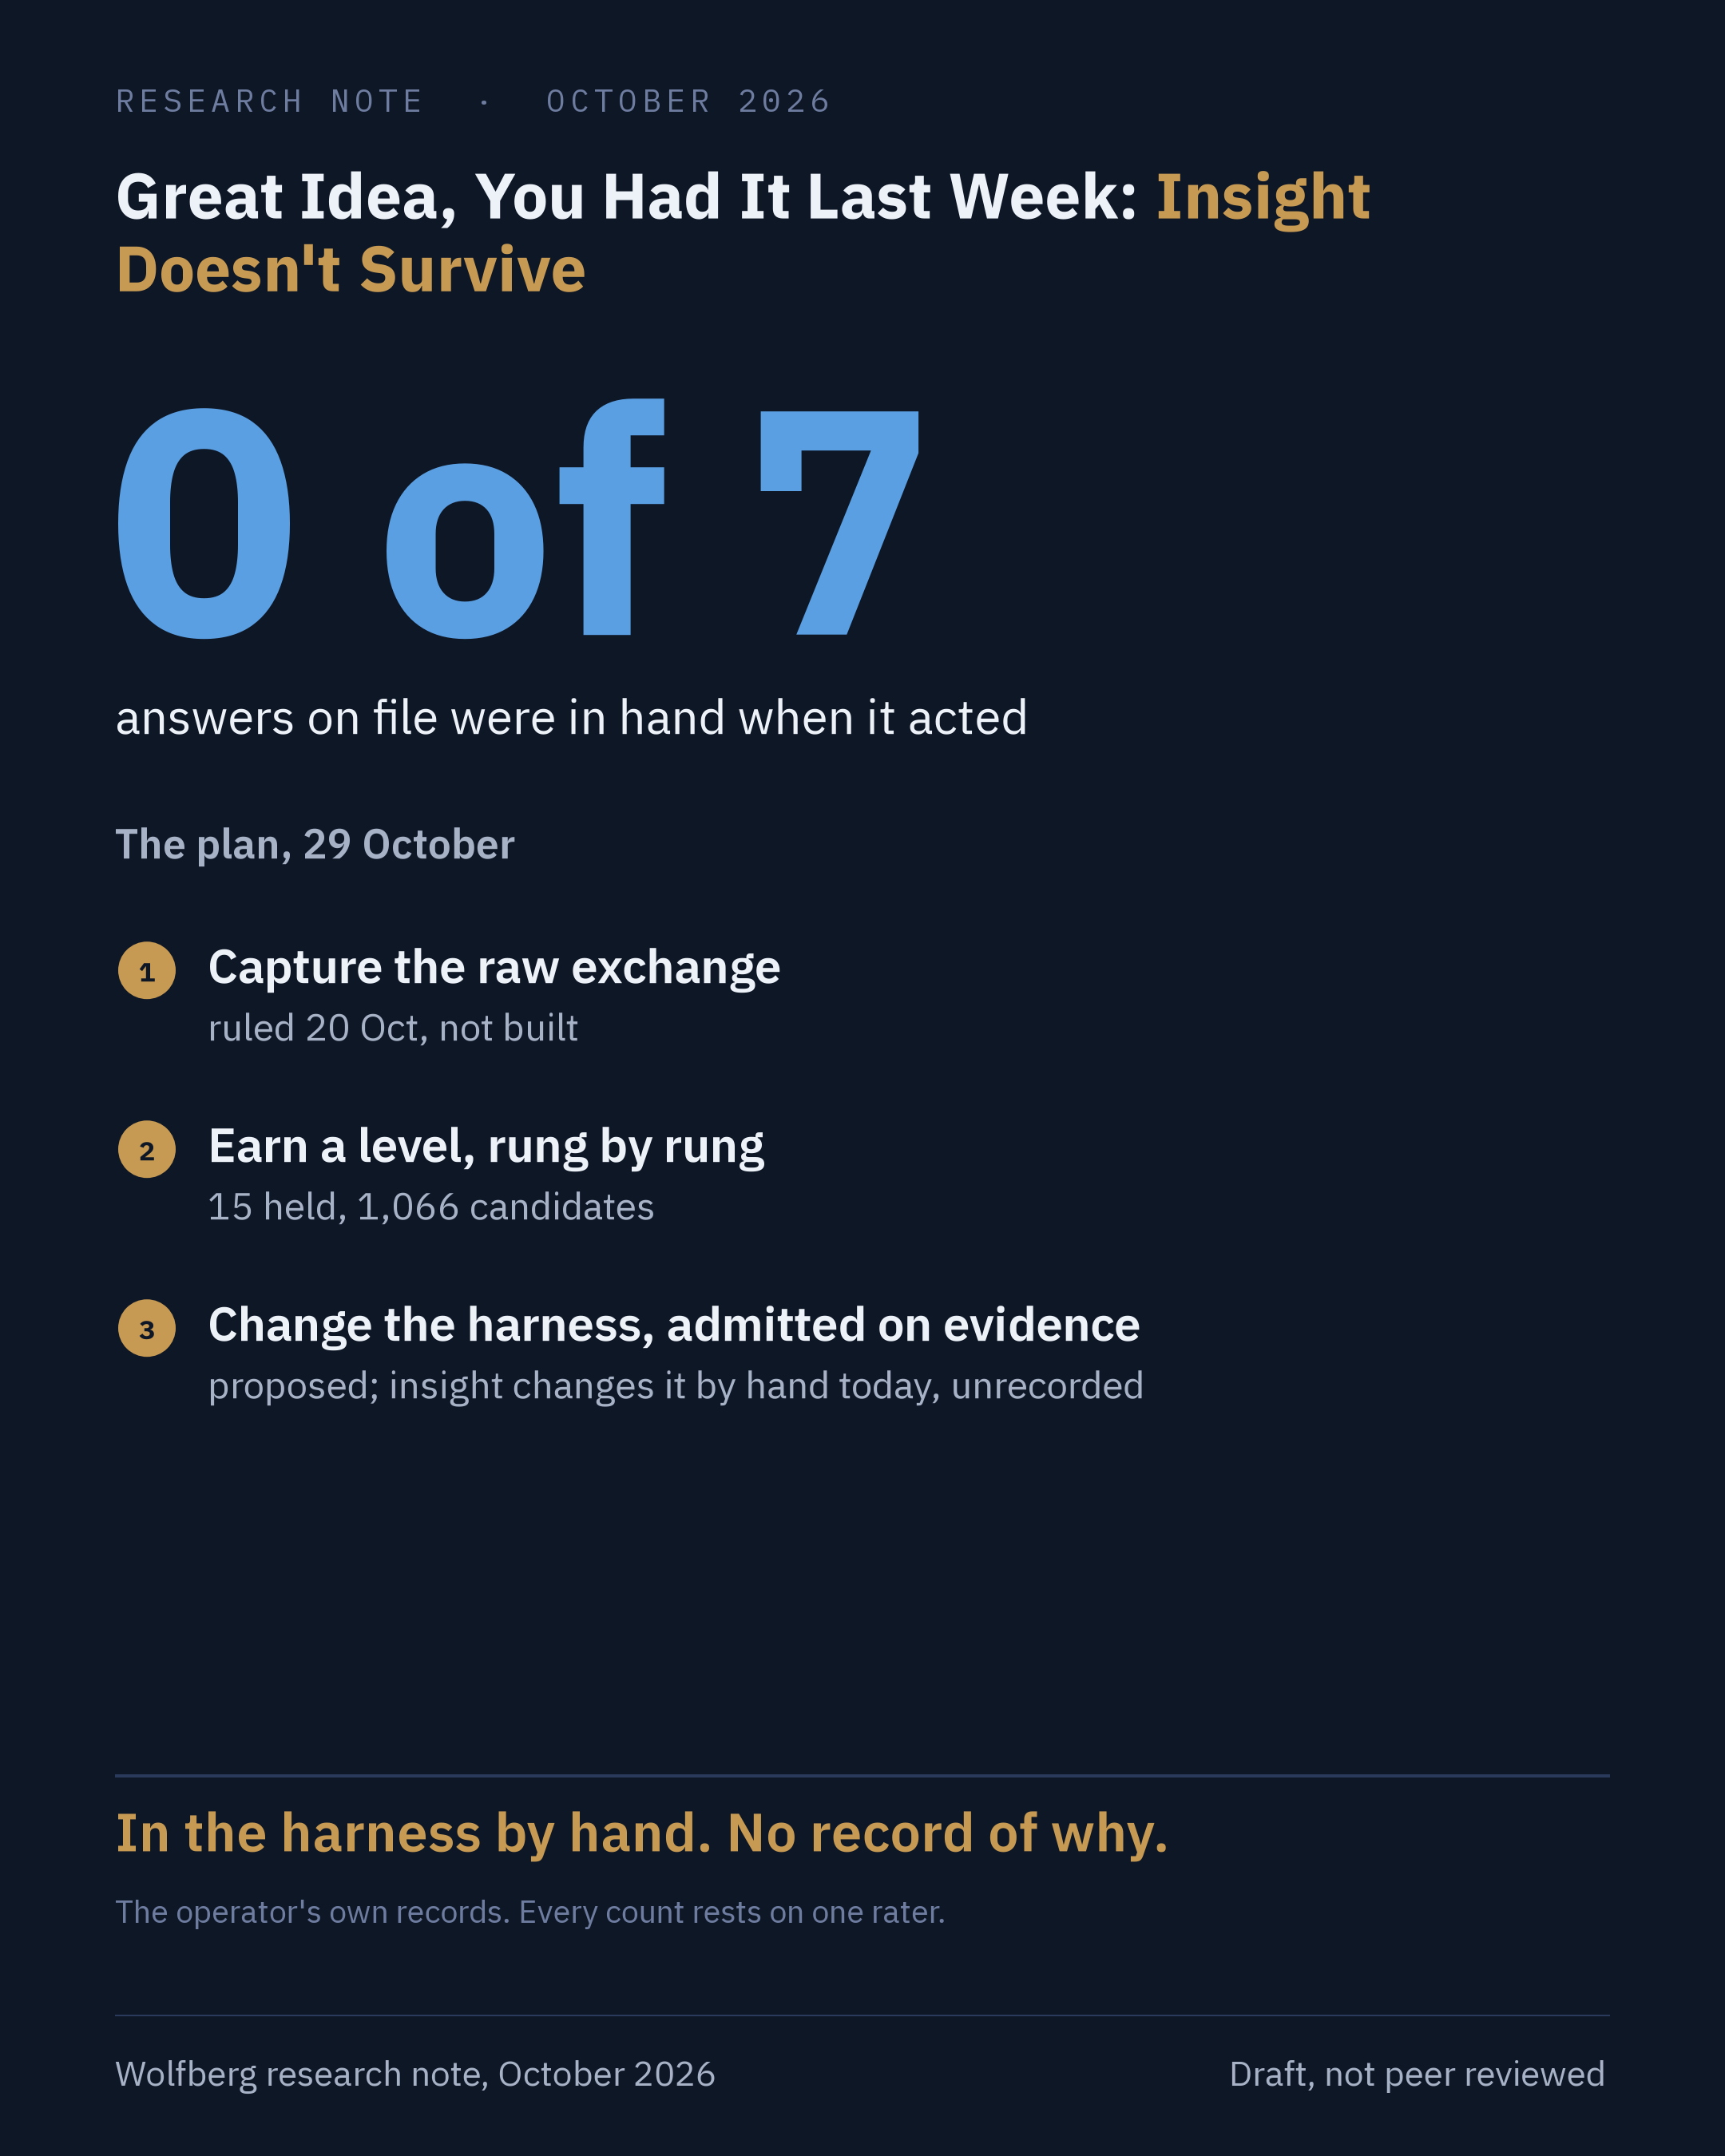
An insight your AI has to go and read loses to the work.
That's rulebook text, and my rules paper showed how well THAT works 🙄 The model doesn't learn between sessions, so an insight only survives as part of the harness (the software around the model), loaded or checked without anyone having to find it. October research says rewriting it into memory, the usual fix, is where the damage happens.
So I had my AI check my own records. On 18 October it gave me seven answers already in my files. Of 34 located losses, 31 crossed a boundary: a different agent, a later session, a compaction. Sorted by the paper's definitions...24 were knowledge, 7 actual insight, and all 7 lost across a boundary. The wisdom? I'm the one dropping the wisdom ha.
My harness DOES get changed from experience, but by hand. Four fixes after things went wrong, and three stuck (replay tests I merged, and two rules my agent landed itself with no sign-off from me on record). I closed the fourth. Insight gets in too: one of those seven answers was an insight and was already in my code, and a second insight sits behind a design that is, with no record of why. The nightly pass meant to automate it ran 43 nights, made 103 proposals, 87 of them prose edits...and one got merged.
Others ARE feeding harnesses from sessions: studies since June turn user corrections into rules and skills. 61 queries in, I couldn't find anyone doing it for insight or wisdom.
Not just me: across 12 other operators' public sessions, 1.6% of lessons ever got a harness edit.
The plan makes insight a recorded input:
- Capture the raw exchange when a position moves. No rewritten lesson.
- Make every record EARN its level: knowledge gets scored as a forecast, insight has to improve those forecasts, wisdom needs my ruling.
- Turn a held record into a harness change (start-up load, procedure, check at the act).
- Admit it only on fresh evidence (or my ruling), judged by something the change can't edit.
Side by side, outside studies | my plan:
- A harness revising itself, admitted on fresh validation (Oct 2026) | same loop, fed by insight
- Lessons bound to the runtime vs readable text: 41.2% vs 34.6%, one study (Sep 2026) | land as mechanisms, not text
- Memory that rewrites the record: 90 of 99 cells below naive retrieval (Oct 2026) | keep the raw exchange
- A check enforced at the stop: +4.0/+5.3 points vs +3.3/+3.9 for just a prompt (Oct 2026) | a lookup at the stop, proposed
Where it stands: 1,066 candidate records waiting on my judgment, 15 confirmed, 0 harness changes from them. Capture is approved, the change step proposed. The loop is not built: the records exist, nothing serves them. If held-record changes don't beat today's harness on replay, the design fails. One practice, one rater (a Claude model reading Claude-written text), and only the losses someone noticed.
An insight that never changes the harness never even gets the chance 🤷♂️
The paper: wolfberg.ai/papers/great-idea-you-had-it-last-week/
Sources
- Wei et al.: Self-Evolving Agent Harness (arXiv:2610.18813, 13 Oct 2026) arxiv.org
- Relic: From Multi-Agent Collaboration to Persistent Organizational Capability (arXiv:2609.32965, 26 Sep 2026) arxiv.org
- He et al.: Memory Tax: Dissecting the Net Value of Agent Memory (arXiv:2610.34073, 25 Oct 2026) arxiv.org
- Zhang et al.: Rethinking Verification in Agent Harnesses (arXiv:2610.34577, 25 Oct 2026) arxiv.org